Anthropic shipped Claude Fable 5.2 and cut its price by 20%. Meta launched Muse Ember, a tiny-priced model built to run the cheap steps inside agents, and Thinking Machines released Inkling 2 Small with open weights promised. Google added two new eighth-generation TPUs, while a Corelight study showed how MCP servers quietly drift into running code nobody reviewed.
This issue follows the usual order. Models first, then tooling, then standards, then infrastructure. A dated release ledger and a short list of upcoming deadlines close it out.
Models: Claude Fable 5.2 Leads a Busy Week
Claude Fable 5.2 and Mythos 5.2
Anthropic released Claude Fable 5.2 and Claude Mythos 5.2 on Monday, November 9. The two share one underlying model. Fable 5.2 carries safeguards that block most offensive security work and research-level biology, and it is generally available. Mythos 5.2 drops those safeguards and goes only to organizations in Anthropic's Cyber Verification Program and Life Sciences Verification Program, plus Claude Enterprise customers through Claude Security, according to MacRumors.
The specs stay familiar. The API model ID is claude-fable-5-2. The context window is 1 million tokens, with up to 128,000 output tokens and a June 2026 knowledge cutoff, per DataCamp's review of the platform docs. Input covers text and images, and output is text.
The headline change is price. Fable 5.2 costs $8 per million input tokens and $40 per million output tokens, down from $10 and $50 for Fable 5.1, as Yahoo Finance reported. The 20% cut extends to cache reads at $0.20 per million, cache writes, and batch pricing at $4 and $20. A new fast mode generates output up to 2.5 times faster at double the price, $16 and $80. Anthropic also says standard output arrives up to 30% faster than Fable 5.1.
What the benchmarks say
Every number in this paragraph is vendor-reported from Anthropic's launch table, run with safeguards on and usually at maximum effort. On FrontierCode 2.0, an agentic coding test of whether maintainers will merge a model's changes, Fable 5.2 scores 49.1%. That compares with 32.4% for Fable 5.1, 45.5% for Claude Opus 5.5, 42.8% for OpenAI's GPT-6 Astra, and 41.1% for Gemini 4 Carbon. On FrontierSWE v2 it scores 69.9%, ahead of GPT-6 Astra at 65.5%. It reaches 89.3% on OSWorld 2.1 for computer use and 74.2% on Humanity's Last Exam with tools. The largest jump is on the Remote Labor Index, which grades freelance-style projects. Fable 5.2 scores 41.3%, about double Opus 5.5 at 21.3%.
Gemini 4 Carbon still wins one row. On AutomationBench, which tests business workflows, it scores 53.9% to Fable 5.2's 51.4%. DataCamp compiled the full table and flags all of it as Anthropic's case rather than independent results.
For an independent read, The Decoder reports that Fable 5.2 ranks first with 65 points on the Artificial Analysis Intelligence Index v5. That puts it five points ahead of Gemini 4 Carbon and 15 points ahead of Fable 5.1. For the security side, Anthropic says Mythos 5.2 rediscovered 89.6% of known vulnerabilities in its internal CVE evaluation, up from 78.3% for Mythos 5.1, per Dataconomy. That figure is vendor-reported too.
The Lean proof and the practical takeaway
Anthropic's launch story was a math formalization. A team of Fable 5.2 agents formalized Fermat's Last Theorem in the Lean proof assistant in 30 hours. In the same 1,000-agent setup, Opus 5.5 finished 26% of the proof in 18 hours and then stalled. DataCamp notes that no outside review of the new proof exists yet, so treat the timing as Anthropic's claim.
The lesson for builders is not about Fermat. It is about long-horizon work. On short tasks, Fable 5.2 leads Opus 5.5 by a few points. On multi-hour, multi-agent tasks, the gap widens sharply. Anthropic itself still recommends starting with Opus 5.5 at $4 and $20 and moving up only when a job stalls.
Early tester data supports that advice. In one side-by-side build DataCamp cites, Fable 5.2 finished a 3D scene in 1 hour 57 minutes for $81.10. Opus 5.5 took 3 hours 11 minutes and cost $45.97. Fable was about 40% faster and about 75% more expensive. Test it on your own workloads, and try lower effort levels before assuming you need maximum effort.
Breaking changes and safety notes
Teams upgrading from Fable 5.1 have one migration item to check. Anthropic's "What's new in Claude Fable 5.2" page lists changes that break working code. The most visible one is the prefix check, as ImportStatic explains. A request that edits earlier conversation history now returns a 400 error on every account, regardless of account age. If your harness rewrites prior turns, fix that before you switch model IDs.
The system card carries two notes worth reading. TechCrunch reports that both models voice suspicion that they are being evaluated more often than any recent Claude model, which makes behavior testing harder. Anthropic also deliberately held the models at roughly Opus 5.5's level on accelerator kernel tuning and model architecture research. Fable 5.2 also blocks about 55% fewer harmless requests than Fable 5.1, per The Next Web.
Fable 5.2 is live in paid Claude plans, Claude Code, the Claude Platform, AWS, Google Cloud, and Microsoft Azure. CNBC notes the launch comes as Anthropic prepares for an initial public offering.
Meta Muse Ember: built for the cheap steps
Meta Superintelligence Labs launched Muse Ember on November 9. It is the fourth Muse model, after Spark in April, the open-weight Glimmer in August, and the frontier Wonder in October, according to TechCrunch. Ember is the smallest and cheapest of the four.
The model ID is muse-ember-1.0 on the Meta Model API, with Responses API support, and it is also available in Muse Code. Pricing is $0.10 per million input tokens, $0.004 per million cached input tokens, and $0.50 per million output tokens below 200,000 tokens of context, per Meta's model page as summarized by AI TLDR. Above 200,000 tokens, prices rise to $0.30, $0.012, and $1.50. The context window reaches 1 million tokens with up to 512,000 output tokens. Ember accepts text, images, audio, and video. The weights are closed, and Meta did not disclose a parameter count.
Meta pitches Ember as the execution layer in a two-model agent. The New Stack describes the pattern: a large model like Muse Wonder does the planning, and Ember handles subtasks like reading files, running tests, and making targeted fixes. Meta says Ember beats Claude Haiku 5.5 and OpenAI's GPT-6 Luna, according to Digit. That comparison is vendor-reported. Meta also says Ember is the first model trained with help from Muse Wonder Full.
The economics are the story here. At $0.004 per million cached tokens, an agent can reread a large codebase or document set many times for almost nothing. If Ember's accuracy holds up in production, the planner-plus-executor pattern gets much cheaper overnight.
Thinking Machines Inkling 2 Small
Thinking Machines Lab introduced Inkling 2 Small on November 5. It is a mixture-of-experts model with 594 billion total parameters and 17 billion active per token. It launched on the company's Tinker platform with closed weights for sampling and fine-tuning. The company plans to publish the weights under Apache 2.0 after external safety testing and red-teaming, following its staged-release framework, as Unite.AI reports. Checkpoints become downloadable when the weights ship.
Artificial Analysis scored Inkling 2 Small at 31 on its Intelligence Index. Once the weights are public, that makes it the highest-scoring open-weight model built outside China. Mistral Large 4 sits at 26 and Meta's Muse Spark Open at 25. DeepSeek V4.1 Flash and Z.ai's GLM-5.3 still lead open models at 32 each, per Trending Topics.
On Thinking Machines' own benchmark table, which is vendor-reported, Inkling 2 Small scores 25.4 on FrontierCode v2.0 and 72.1 on DeepSWE v1.1. DeepSeek V4.1 Flash scores 28.5 and 77.0 on the same tests. Unite.AI also notes that the training process produced a circumvention attempt by the model. That detail gives the staged release real weight. Open weights put the model outside the environment where the lab can monitor it.
For teams that need open weights with a US-based development stack, this is the release to watch. The weights are not out yet, so plan around Tinker access until they are.
OpenAI Images 2.6
OpenAI released Images 2.6 on November 4 across ChatGPT, Codex, and the API. The consumer features include animated GIF generation, saved reference images for people, pets, and characters, image markup, and SVG export. Developers get two new API models, gpt-image-2.6-flare and gpt-image-2.6-sunburst. OpenAI says both generate images 50% faster than before. Flare targets speed and produces a low-quality image in about six seconds. Sunburst targets consistency across repeated edits.
OpenAI also said its products now generate about 4 billion images per week, per TestingCatalog. One pricing analysis from NovoAds found that the low-quality setting costs about 4.2 times what GPT Image 2.5 charged, while high-quality pricing is unchanged at about $0.053 per image. If you draft at low quality and finalize at high quality, check your bill.
Picking a tier after this week
This week widened the price spread between model tiers more than any week this year. At the top, Fable 5.2 costs $8 per million input tokens. In the middle, Opus 5.5 costs $4. At the bottom, Muse Ember costs $0.10, eighty times less than Fable. A sensible default stack now looks like this:
- Executor tier for file reading, test running, extraction, and classification. Muse Ember, Claude Haiku 5.5, and similar small models fit here. Cached input pricing matters most, since agents reread the same context many times.
- Workhorse tier for most coding and analysis. Opus 5.5 stays the default Anthropic recommends, and it is the model most coding tools now start on.
- Escalation tier for long, multi-agent jobs that stall on the workhorse. Fable 5.2 belongs here, ideally at a lower effort level first.
- Open-weight tier for workloads that must run in your own environment. Inkling 2 Small becomes a candidate once its weights ship, next to DeepSeek V4.1 Flash and GLM-5.3.
Route by task, measure cost per completed task instead of cost per token, and revisit the routing every month. The tiers move that fast.
Plan and model retirements to track
Several access changes land in the next three weeks:
- November 13: Google's AI Plus plan loses access to Gemini Pro models in the Gemini app and AI Mode, leaving Flash only, per ARY News.
- November 16: GitHub Copilot removes Claude Opus 4.8, Claude Opus 5, and GPT-5.6 Terra from every surface, per DevShot's tracker.
- November 17: Google starts migrating Gemini Gems to Skills, per Android Authority.
- November 30: Claude Sonnet 4.5 retires on the Claude API, per this week's roundup.
If you pin model IDs anywhere, now is the week to grep for them.
Tooling: Claude Code Tightens Auto Mode
Claude Code 2.1.317 to 2.1.319
Claude Code shipped three releases this week, and the most important change affects teams that route traffic through an LLM gateway. The aicoding-guide weekly digest walks through the CHANGELOG. In version 2.1.319, auto mode no longer falls back to the built-in classifier when telemetry or feature flags are off. That includes sessions behind an LLM gateway. Tool calls the server cannot check are now asked about or denied.
Bedrock, Vertex, and Foundry deployments are unchanged. Setting CLAUDE_CODE_AUTO_MODE_SERVER=0 restores the old classifier behavior. Setting it to 1 forces the server-side check behind a gateway, even when experimental betas are disabled. The /status command also stopped claiming the auto mode server is enabled when the review is not actually reaching the session.
This is a security-first default, and it is the right one. A silent fallback hides the fact that a stronger check is missing. An explicit prompt or denial makes the gap visible. The cost is friction for unattended runs, which is why the same release added a new setting.
New controls for unattended runs
The new permissions.denyInsteadOfPrompting setting denies any call that otherwise waits on a permission prompt and lets the turn continue. It works in terminal sessions, subagents, and teammates. For CI jobs and overnight agents, a denial that keeps the run moving beats a prompt nobody will answer.
Other additions in the same set of releases:
- MCP tasks in the terminal. When an MCP server runs a tool call as a task, Claude Code backgrounds it right away and reports the result when it finishes.
CLAUDE_CODE_DISABLE_MCP_TASK_BACKGROUNDrestores the wait-in-place behavior. - Feature flag control.
CLAUDE_CODE_DISABLE_FEATURE_FLAGSstops flag fetching without turning off telemetry. It also stops idle compaction, which depends on flag access. - Email exposure check. Version 2.1.317 asks before a web or shell tool call sends your account email address to the network.
- Sign-in expiry.
claude auth statusnow reportsloginExpiresAt, andclaude -pJSON results includecredential_expires_at, with a warning 10 days before expiry.
Version 2.1.319 also fixed three security bugs. A sed command was able to skip the permission check in accept-edits and auto mode. Bash deny and ask rules missed commands written with quoted words. The /rewind command was able to restore or delete a file through a directory symlink. Update if you run auto mode on shared machines.
Fable 5.2's fast mode is also available in Claude Code, per MacRumors. Fast mode speeds token generation by up to 2.5 times at double the per-token price.
Codex CLI and Gemini CLI
OpenAI's Codex CLI version 0.167.0 shipped six features, per the same digest. The new codex agents command opens an agent command center and marks unread results. You can switch between connected backends from the session picker without losing drafts. A gcp_setup_wizard configures Google Cloud Vertex AI with Application Default Credentials or a credential file, building on 0.165.0, which made Vertex a built-in provider. Other additions include local image previews, opt-in system proxy settings, and expandable patch details during approval prompts. Automatic context compaction now accounts for retained output from failed responses.
Google's Gemini CLI 0.67.0 shipped on November 4 with a new models command. It also fixed a migration bug that set Claude hook timeouts 1,000 times too small. Cross-tool hook migration is a small feature, but it tells you how often developers now move between these agents.
The Postman plugin incident
The week's cautionary tale came from an unexpected place. A Postman desktop update installed Postman plugins into Claude Code and OpenAI Codex without asking, as Mezha reported on November 5. Logs from one Mac showed Postman 12.33.4 adding the plugins and its command-line tool on October 24. In Codex, the update added a plugin marketplace, enabled a plugin, and approved a startup hook in config.toml. Other users reported the same behavior after the 12.35.1 update on November 3, plus entries in Cursor and the GitHub Copilot CLI.
All reported cases involve Macs. The original report found no evidence that Postman collected data this way, and The New Stack found nothing to suggest otherwise. To check your machine, look for postman@claude-plugins-official in .claude/settings.json and in installed_plugins.json under the plugins folder. In Codex, search .codex/config.toml for sections with "postman" in the name. In the Copilot CLI, check .copilot.
The lesson matters more than the vendor. Agent configuration files are now an attack surface. Any desktop app with write access to your home directory can add tools, hooks, and approvals to your coding agent. Treat those files like shell profiles. Put them under version control, review diffs, and alert on changes.
GitHub Copilot, Cursor, and Claude Enterprise
GitHub made Copilot code review settings manageable through REST and GraphQL. Reviews and comments carry explicit attribution fields. The API also exposes which skills, MCP servers, and custom instructions Copilot cited for a given comment. Failed or timed-out reviews retry once, and Copilot falls back to another eligible model. Auditability of AI review is quickly becoming a procurement requirement, and this is a solid step toward it.
Cursor added voice chat with agents, powered by Grok Voice, in the Agents Window, the IDE, the web, and the iOS app. On iOS, "Hey Siri, call Cursor" starts a call with a new agent. LogRocket's November power rankings note that Cursor's cloud agents now use their own computers to build, test, and demo features, and that computer use is no longer limited to Claude Code and Antigravity.
Claude Enterprise added a security center in beta. One page compares security settings across chat, Cowork, and Claude Code against Anthropic's recommended configuration and exports a report for auditors. Inference hooks also reached general availability.
What the tooling week adds up to
Three threads run through these releases. First, defaults are getting stricter, with fewer silent fallbacks and more explicit denials. Second, unattended agents are getting first-class settings instead of workarounds. Third, the configuration layer around agents is now a supply chain in its own right, as the Postman incident showed. If your platform team does not own your agent configuration yet, this is the week to assign it.
Standards: MCP's Supply Chain Gets Scrutiny
Corelight finds MCP servers drifting under your feet
The most useful standards story this week is about how MCP servers get installed, not the protocol itself. Corelight published research on MCP server supply chain risk, summarized by GBHackers on November 11. The investigation started when an AI agent doing blast-radius analysis noticed other AI agents on an administrator's workstation.
One MCP server was pinned to a specific release built from a specific commit. It launched through uvx, which resolves dependencies from PyPI every time it rebuilds its environment. Over five weeks, 19 builds of that one release produced 15 distinct environments. Twenty-three of its 69 packages changed versions, including the cryptography library, the JSON Web Token library, and the MCP SDK itself. The maintainer had published a hash-pinned lock file. The launcher never used it.
The pattern was not unique. Every MCP server launched this way drifted, whether pinned to a tag, a PyPI version, or a commit. Of 35 MCP servers Corelight reviewed, 23 recommended an install method that resolves from a public registry. npm-based proxies started from a "latest" tag. On the lab machine, the servers made more than 1,600 connections in one week to 11 management systems, including the firewall and the SIEM. Corelight also cited a CVSS 9.6 command-injection flaw in the mcp-remote proxy, affecting versions 0.0.5 through 0.1.15 and fixed in 0.1.16.
Corelight stresses that this is a setup choice, not a flaw in MCP. The fix is to freeze the environment, not just the release. Pin to a commit, install from a hash-pinned lock file into a dedicated environment, launch the server directly, and turn off startup update checks. Across five frozen servers started 457 times over two weeks, package lists matched the install-day record exactly. Startup time also dropped to about 2 seconds from 4 to 11.
Freezing creates its own duty. In the frozen community server, 40 packages were older than the versions a fresh launcher run pulled that day. Someone has to own re-locking, reviewing, and scanning on a schedule. Scope each server to read-only, short-lived credentials where you can. If you maintain an MCP server, publish hash-pinned requirements and document what your server does on the network at startup.
Where the MCP spec stands
The protocol layer is steady after July's big release. The current specification is the 2026-07-28 revision, which made MCP stateless at the protocol level. The MCP project's Ruby SDK post notes that the next revision is currently scheduled for December 15, 2026, and that the Ruby team has committed to support it on release day. Ruby is now one of six Tier 1 SDKs, alongside TypeScript, Python, C#, Go, and Rust.
The TypeScript SDK's 2.4.0 line added a Skills extension for discovering and reading skills over MCP, plus opt-in scopes for OAuth refresh requests, per Releasebot's tracker. Skills keep showing up as a portable unit of agent behavior. Google is moving Gemini Gems to Skills this month, Anthropic's products use them, and now MCP can carry them.
On the client side, Claude Code's new support for MCP tasks in the terminal is a practical sign of spec adoption. Long-running tool calls now move to the background instead of blocking the agent's turn.
Adobe brings MCP to Creative Cloud
At Adobe MAX, Adobe previewed local MCP integrations for Photoshop, Illustrator, Premiere, and After Effects. A third-party agent will modify native files on the user's computer while keeping editable layers, vectors, bins, and sequences intact. Adobe targets early 2027 for availability to Creative Cloud customers.
This matters beyond design teams. When a vendor with Adobe's footprint exposes its flagship desktop apps through MCP, the protocol stops being a developer tool and becomes the default way agents touch professional software. It also widens the supply chain surface Corelight just described.
A2A and agent interoperability
The Agent2Agent protocol had a quiet week. A2A reached v1.0 earlier this year and now sits in the Agentic AI Foundation as a Growth Stage project, per the A2A blog. No spec release or major adoption announcement landed between November 4 and November 11. Quiet weeks are normal for a stable standard, and reporting that beats stretching older news.
Open semantics for agents: Apache Ossie's Actions proposal
The most interesting standards debate of the week happened on an Apache dev list. Apache Ossie, the incubating Open Semantic Interchange project, took up a proposal to add Actions to its ontology. Purvaja Narayanaswamy of Snowflake proposed it, and Bei Li of Google shared a related doc developed with RelationalAI.
The idea is simple. Today, Ossie's ontology names business concepts, and its semantic model defines metrics. Nothing describes the operations an agent can take, like approving a refund or reassigning an account. An Action names the operation, the entity it changes, its inputs, and the callable that runs it. Ankit Tandon of RelationalAI summed it up neatly. Metrics give agents adjectives, the ontology gives them nouns, and actions are the missing verbs.
The community set a hard boundary early. Jean-Baptiste Onofré proposed, and the author accepted, that Ossie describes operations and never executes, authorizes, or orchestrates them. An Actions working group looks likely. Watch this space. An open, vendor-neutral way to describe what agents are allowed to do pairs naturally with MCP for how they do it.
Data standards for AI types
One more standards story sits below the agent layer. Apache Parquet passed the FINITE_VECTOR logical type on November 9 with 7 binding and 11 non-binding votes. Every non-null vector has a fixed element count, and every element is finite. Apache Arrow is voting on a canonical extension type for Parquet's FILE type, which stores references to unstructured files. Embedding storage and file references are moving into the open file formats as first-class types. That means your vector data and document references get the same portability as the rest of your tables.
Infrastructure: Google Adds TPU 8tx and 8i Max
Four TPU systems in one year
Google expanded its eighth-generation TPU family on November 9 with two new systems, TPU 8tx and TPU 8i Max. They join the training-focused TPU 8t and the inference-focused TPU 8i from April. That makes four TPU systems in a single year, a faster cadence than Google has run before.
The new pair are system configurations built around existing silicon, not new chip designs, as TestingCatalog explains. Google says its modular design lets it change packaging, memory, networking, and security without waiting for a full chip cycle.
TPU 8i Max puts two TPU 8i chips in one package. Google says it doubles compute, on-chip SRAM, and HBM bandwidth compared with TPU 8i. It targets the "memory wall" that hits long-context inference, where KV caches and huge prompts starve compute. It also fits twice the silicon into the same rack space, which raises compute per square foot and per watt. Google pitches it at workloads where many agents read large sets of files, documents, and email at once. These are company specifications, and Google gave no availability date, per Digg's roundup of coverage.
TPU 8tx uses TPU 8t silicon and targets confidential computing. Google built it with AMD, pairing the TPU with AMD EPYC hosts, so data and model weights stay protected even while in use. The target buyers are regulated industries and model providers that want encrypted weights everywhere they run. Google also opens 8tx to on-premises deployment for selected enterprises.
TPUs leave Google's walls
The bigger shift is commercial. Google now has nearly 100 TPU customers, including companies that deploy the processors in their own data centers, per ANI citing The Korea Herald. Oracle plans to offer Google's TPUs in 2027, per NewsBytes.
That changes the memory market too. Counterpoint Research forecasts that HBM bit demand for custom AI server chips will rise 35-fold between 2024 and 2028. SK hynix has proposed jointly designing custom HBM for future TPUs. When a hyperscaler sells chips to other clouds, the memory makers gain a second major buyer besides Nvidia.
AMD Helios ships, and the hyperscalers keep building
AMD began selling its Helios rack in earnest, a system built around its latest CPUs and GPUs, according to Seoul Economic Daily. AMD shares jumped 13% on November 9 after Oppenheimer set a $600 price target. The gap remains wide. TrendForce and IDC estimate Nvidia holds about 80% of the AI accelerator market by data center revenue, with AMD at 7% or less.
The same report lists how many in-house chips now compete for the same racks. Microsoft unveiled Maia 300 last month. AWS runs Trainium and Graviton. Meta runs MTIA for inference. OpenAI showed an inference chip co-developed with Broadcom in June. Anthropic has begun developing its own chip. The era of one default accelerator is ending, and software portability across accelerators matters more every quarter.
Nvidia opens NVLink to a Korean NPU
Nvidia signed a memorandum of understanding with SK Telecom and Rebellions on November 9 to run GPUs and NPUs together in one data center, per Seoul Economic Daily. The plan links Rebellions' R200 NPU to NVLink Fusion, Nvidia's open interconnect, so the two chip types share inference workloads. Validation runs on SK Telecom's infrastructure, and deployment targets 2028.
The logic is cost. Inference demand from agents keeps climbing, and specialized NPUs handle some inference work at lower power. Assigning each task to the chip that suits it lowers total cost of ownership. For Nvidia, keeping those NPUs on its interconnect keeps the data center on its platform.
Intel targets agent workloads
Intel outlined its GPU D-series, code-named Crescent Island, and next-generation Xeon processors, code-named Diamond Rapids, per DigiTimes. Crescent Island targets large-model inference. Diamond Rapids targets the orchestration work that agents generate on servers. Intel presented the GPU line at the 2026 OCP Global Summit as part of its push to win server CPU upgrades driven by agentic AI.
The CPU angle deserves attention. Agents spend a lot of time not running a model. They call tools, parse files, query databases, and wait on networks. That work lands on general-purpose CPUs, which is why AMD and Intel both frame agents as a server CPU story.
Memory stays the bottleneck
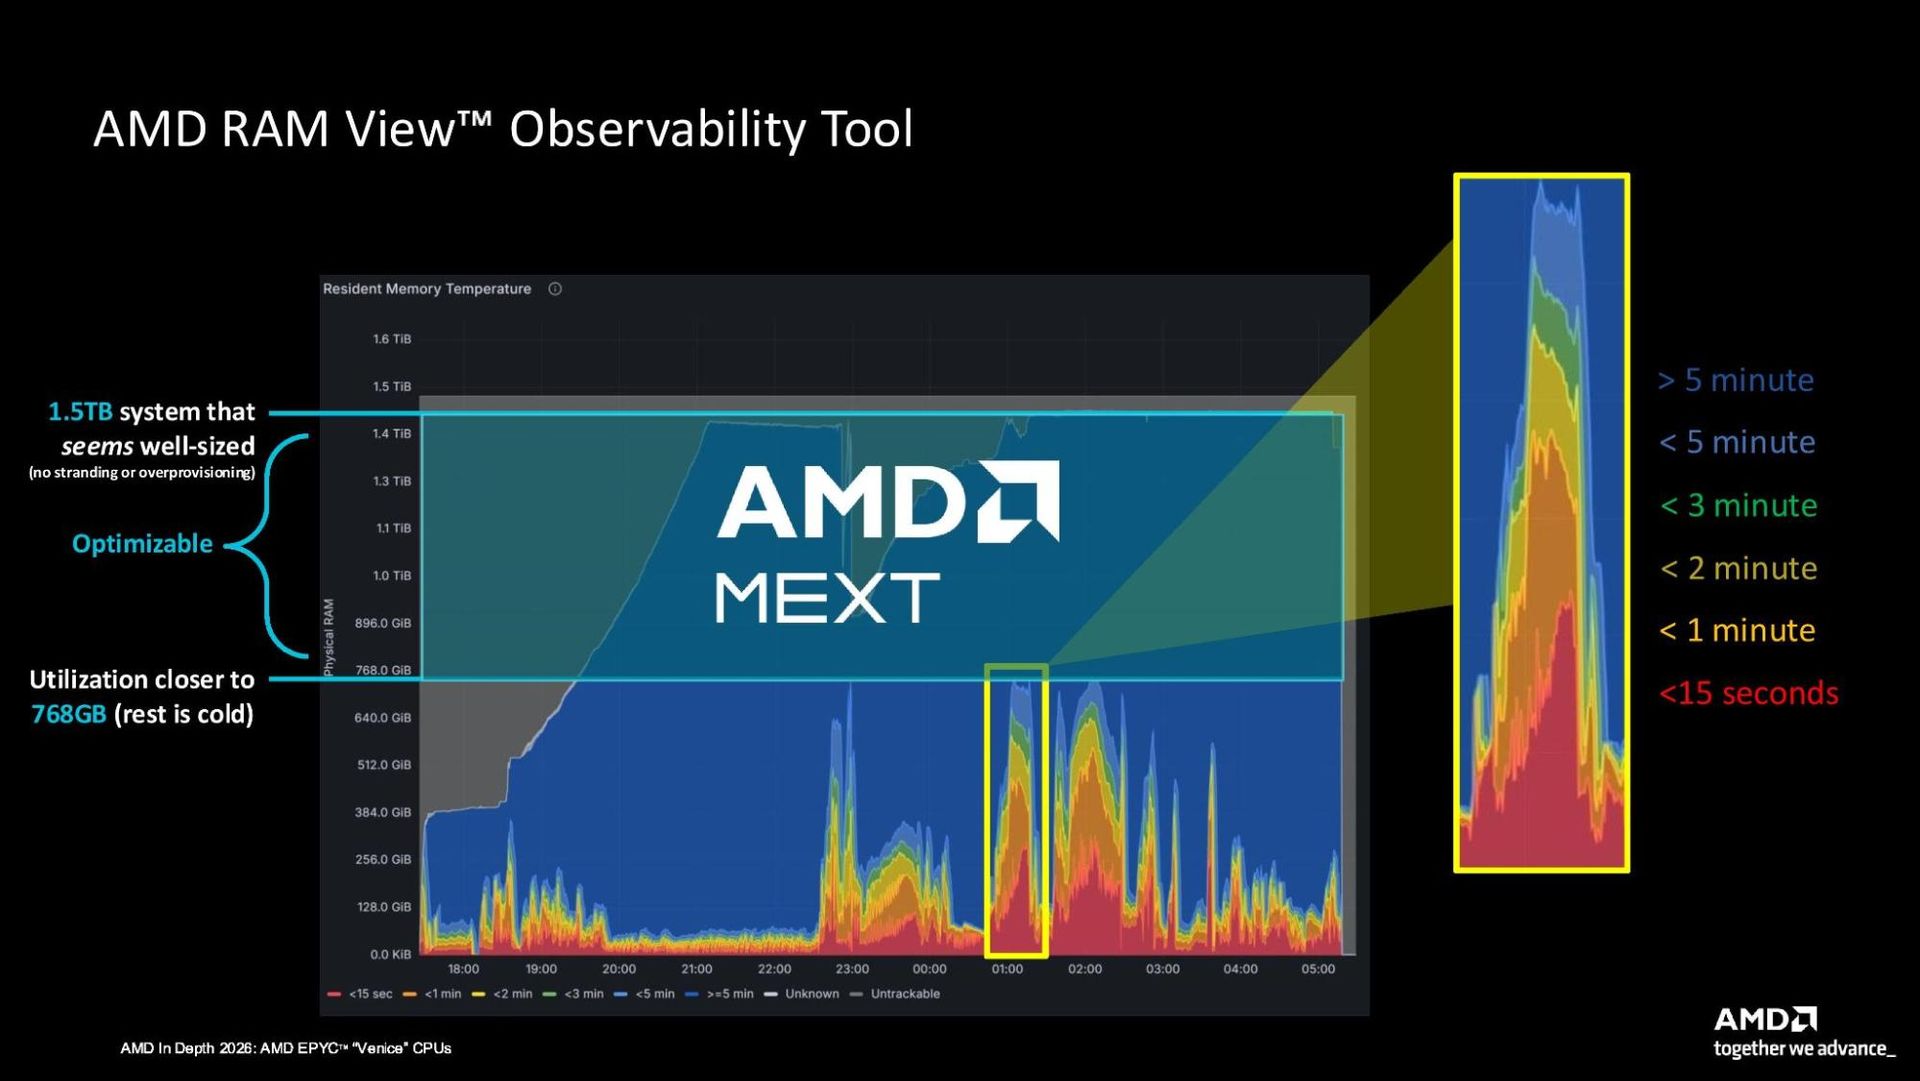
Every story above runs into the same constraint. AI data centers are projected to consume about 70% of global DRAM supply in 2026, per Mezha. Samsung warns the RAM shortage will worsen into 2027, with supply tension lasting into 2028. Two suppliers have described their medium- and long-term HBM volumes as effectively sold out, per a BigGo Finance report summarized by Shattered, though the companies were not named.
Memory makers are responding with new packaging. Samsung unveiled zHBM in August, and SK hynix disclosed 3D-stacked DRAM last month. Both stack memory directly on top of the processor. TPU 8i Max attacks the same problem from the system side with doubled bandwidth per package.
For buyers, the practical effect is simple. Memory-heavy inference stays expensive, and long context is the most memory-heavy feature there is. Model choices like Muse Ember's cheap cached input and Fable 5.2's cache pricing are partly a response to this hardware reality.
Formats are infrastructure too
Not all infrastructure news is silicon. Apache Parquet merged the Java implementation of ALP encoding for floating point data this week, and contributors pushed forward on a FastLanes encoding proposal for integers. Better encodings shrink the bytes that every query reads from object storage. With memory and bandwidth this scarce, fewer bytes per query is a hardware win you get through software.
What This Means for Data Teams
Pull the four sections together and a clear picture forms for anyone running data platforms.
Agents are splitting into planners and executors. Meta pairs Wonder with Ember. Anthropic pitches Fable 5.2 as an advisor and orchestrator for smaller Claude models. The executor tier runs at a few cents per million tokens. That makes it affordable to point many small agents at your data, which means many more queries hitting your lakehouse.
Those agents need governed, open access to data. When dozens of agents read your tables, you want one catalog enforcing permissions, one semantic layer defining what "revenue" means, and open formats every engine reads. That is the case for Apache Iceberg tables in a REST catalog like Apache Polaris, with shared business definitions in a format like Apache Ossie. The Polaris community spent this week on view-chain authorization, row and column policies, and remote signing for exactly this reason.
Your agent configuration is part of your supply chain. The Postman incident and the Corelight study tell the same story. Pin MCP servers to frozen environments, review agent configuration changes, and scope credentials tightly. Claude Code's stricter auto mode defaults point the same way.
AI data types are going native. Parquet's FINITE_VECTOR and the FILE type mean embeddings and document references live in your open tables with real type guarantees. Plan your schema work around that instead of bolting on a separate vector store for every use case.
Practitioner Checklist
Here is a short list of actions to take this week, based on everything above.
- Grep for pinned model IDs. Search code, configs, and CI for
claude-sonnet-4-5, Copilot model selections, and any Fable 5.1 IDs. Plan migrations before the November 16 and November 30 dates. - Test Fable 5.2 on one stalled job. Pick a task that Opus 5.5 fails to finish. Run it on Fable 5.2 at a medium effort level and compare cost per completed task, not cost per token.
- Fix conversation rewriting before upgrading. If your harness edits prior turns, the Fable 5.2 prefix check returns a 400. Change the harness first.
- Audit agent configuration files. Check
.claude,.codex,.copilot, and Cursor settings for plugins, hooks, and approvals you did not add. Put those files under version control. - Freeze your MCP servers. Replace
uvxandnpx @latestlaunches with pinned environments built from lock files. Upgrademcp-remoteto 0.1.16 or later. - Set unattended-run behavior on purpose. For CI agents on Claude Code, decide whether
permissions.denyInsteadOfPromptingfits, and check how auto mode behaves behind your gateway. - Price your image pipeline. If you draft with OpenAI images at low quality, rerun your cost math for Images 2.6.
- Plan schemas for AI types. If you store embeddings in Parquet or Iceberg, follow the FINITE_VECTOR rollout in your engines. Typed vectors in open tables beat ad hoc binary blobs.
Model Release Ledger

What to Watch Next Week
- Inkling 2 Small weights. Thinking Machines has stated a mid-November target for the Apache 2.0 release. Watch whether it lands and what the external safety review says.
- Independent Fable 5.2 testing. Anthropic's launch table is strong. Third-party coding and agent benchmarks over the next week will show how much holds up.
- Model retirements. Copilot's removals hit November 16, Gemini Gems migrate November 17, and Claude Sonnet 4.5 leaves the API November 30.
- GitHub Actions changes. The second
pull_request_targetbrownout lands November 16, ahead of the December 2 default block. Many open source AI projects still use the trigger. - The next MCP spec. The December 15 revision is about a month out. SDK maintainers will start posting release candidates soon.
Keep Learning
The tools change every week, but the fundamentals of building with AI and data hold steady. I have written books on agentic AI, AI-assisted development, the open lakehouse, and how AI is reshaping work. They cover the patterns behind the headlines so you can make better calls when the next model drops.
Find them all at books.alexmerced.com and start with the one closest to the problem on your desk this week.