Over the past year, AI agents have moved from exploration into engineering. Enterprise teams are shipping large language model (LLM) systems that call tools, orchestrate APIs, and answer questions over internal knowledge.
A successful demo can show what an agent is capable of. Before release, the team needs to answer a further question: “Is this agent ready for production?” The person responsible for that decision needs evidence that the agent meets the agreed requirements.
To make that decision consistently, teams need a repeatable, affordable way to assess the agent’s current behavior and whether the latest change has improved it.
In traditional software development, teams answer these questions with unit tests, continuous integration and continuous delivery (CI/CD), and passing builds. Those mechanisms are necessary but not sufficient for agents, for three reasons, each requiring additional checks. This post explains these three properties and presents a measured case where an aggregate metric hides a coverage problem. It then introduces the Agent Development Lifecycle (Agent DLC): one lifecycle, two loops, and a single explicit standard for judging every change.
A note on terminology: Throughout this post, gold standard means one specific artifact: the bundle of verifiable criteria, their thresholds, and the approved examples they are checked against. Business owners approve this standard as the basis for acceptance decisions.
1. Three properties of agents that require additional engineering practices
Conventional software testing and CI/CD still apply to agents, but three properties require additional checks. First, agents are non-deterministic: identical inputs can produce different outputs and execution paths. Second, changes to prompts, tool descriptions, retrieval settings, or memory configuration can alter behavior in ways that a text review alone can’t reveal. Third, model endpoints, knowledge bases, and external APIs can change independently of the repository and affect agent behavior. Table 1 summarizes the engineering practices needed to address each property.
Table 1. What each property invalidates, and what it requires instead.
| Property | The conventional answer | Why it falls short | What Agent DLC requires |
| Non-determinism | One assertion per case in CI | Measures a single sample of a distribution. Passes and fails for reasons unrelated to your change | Run each example k times. Judge on pass rate and failure distribution |
| Prompts are source code | Review the diff, approve the change | Behavior can’t be read off the text of a prompt | Every prompt, tool, retrieval, and memory change is versioned with an evaluation attached, and the lineage is kept |
| Dependencies move on their own | Pin versions, validate on upgrade | Doesn’t fire because nothing in your repository changed | Re-run the standard on a schedule and alert on deviations from the baseline |
2. A measured example: High retrieval precision can hide missing information
The following example shows how the choice of metrics affects diagnosis.
We built a reference implementation to exercise the method end to end: an internal policy assistant answering HR policy questions over a document knowledge base. We chose a narrow, well-scoped domain to make the evaluation and diagnosis straightforward to follow. The following results were measured on this reference implementation. It isn’t a customer outcome and it isn’t a benchmark result.
The accompanying AWS Samples repository includes infrastructure deployment, the HR agent, custom evaluators, and scripts for baseline evaluation and prompt-change re-evaluation (09-run-eval.sh and 10-optimize-prompt.sh). It also includes optional checks for judge repeatability, model comparison, cost, and latency. The scripts reproduce the workflow. Scores can vary across runs and repository versions.
Three golden questions, five measures each:
- Groundedness: Decompose the answer into claims and check each against the retrieved sources.
- Chunk-level source precision: Is each retrieved chunk, as a whole, necessary for this question?
- Fact-level source precision: Decompose each chunk into individual facts and check whether each fact is necessary.
- Retrieval coverage: For each sub-question, does any retrieved chunk answer it?
- Response precision: Of the claims in the answer, how many are necessary?
Table 2. First evaluation round. Measured on the reference implementation. Not a customer outcome.
| Question | Groundedness | Chunk-level precision | Fact-level precision | Retrieval coverage | Verdict |
| Performance review | 0.83 | 1.00 | 0.59 | 1.00 | Pass |
| Benefits enrollment | 0.90 | 1.00 | 0.53 | 1.00 | Pass |
| Sick-leave certificate | 0.39 | 1.00 | 0.09 | 0.00 | Fail |
Chunk-level precision is 1.00 for all three questions. A release gate based only on this metric would accept all three answers.
Fact-level precision tells a different story: 0.59, 0.53, 0.09. For the third question, roughly nine out of ten facts in the retrieved material are irrelevant to what was asked. Chunk-level precision only asks whether a passage is on topic. It doesn’t measure how much of the passage is relevant.
Then we changed exactly one thing: the system prompt. We added three constraints: ground strictly in retrieved content, ignore irrelevant retrieved content, and keep answers focused. The agent, the knowledge base, the evaluators, and the questions were untouched, so the before-and-after differs by one variable.
Table 3. After a prompt-only change. One change, two opposite outcomes.
| Performance review, before | Performance review, after | Sick leave, before | Sick leave, after | |
| Groundedness | 0.83 | 0.87 | 0.39 (fail) | 0.31 (still fail) |
| Fact-level precision | 0.59 | 0.85 | 0.09 | 0.04 |
| Response precision | 0.58 | 0.73 | 0.33 | — |
The first question improved substantially. The third got worse.
The evaluation suggested where to investigate before we made the change. Look at the third row of Table 2 again: chunk-level precision 1.00, fact-level precision 0.09, retrieval coverage 0.00. Together, these scores suggested a knowledge-coverage problem: the retrieved material was nominally on topic but didn’t answer the question. Telling the model to “ground strictly in retrieved content” couldn’t supply the missing information.
We checked that diagnosis against the source documents used in the experiment. The corpus lacked a dedicated sick-leave policy document, although the leave-management policy contained brief references to sick leave. The next step was to address policy coverage and then check retrieval, rather than keep changing the prompt.
In this case, the source material lacks the information needed to answer the question, so prompt changes alone can’t resolve the failure.
In this example, evaluation helped identify what needed investigation before further changes.
Another result shows why groundedness needs to be checked alongside other criteria. The benefits-enrollment answer passed with groundedness 0.90, and it contained this sentence: “I also noticed from your profile that your preferred contact method is Social Media.” No such profile exists.
The policy document lists contact preference as an option inside a process step. The public, crowd-sourced, noisy FAQ corpus contains a pair answering that question with “social media”. The model combined a policy option with an unrelated FAQ answer and presented it as a fact about the user. The high groundedness score didn’t catch this false personal claim. Passing a quality threshold doesn’t establish that responsibility constraints have been met.
These scores can vary between runs, and a borderline Pass can become a Fail. Interpret score differences alongside repeated runs and the underlying evidence. Section 5 discusses how to check evaluator reliability.
This small reference-implementation example illustrates how evaluation can guide diagnosis. It doesn’t establish a general improvement rate or validate a production release.
3. Agent DLC: One lifecycle, two loops
Agent DLC connects six activities around one explicit gold standard: Define, Build, Evaluate, Release, Observe, and Feed Back.
Evaluation-driven development has been described in earlier work, including Xia et al.’s Evaluation-Driven Development of LLM Agents: A Process Model and Reference Architecture. Agent DLC applies this approach to delivery through six activities with explicit acceptance conditions, release authority, and evidence requirements.
The acceptance-first approach also appears in Fotor’s published AWS customer case study. The team defined scalability, cost, isolation, and architectural flexibility criteria before migrating to AgentCore runtime, a capability of Amazon Bedrock AgentCore, then validated changes against operating data. The case reports workflow overhead falling from minutes to seconds, excluding model inference, and support for thousands of concurrent active sessions. It documents Agent DLC-guided architecture delivery. Quality evaluation is identified as the next step.
Define translates business objectives into criteria, thresholds, and approved examples. Build designs the prompts, tools, context, memory, and runtime mechanisms that must satisfy them. Evaluate produces the evidence that says whether a candidate version does. When it does, the version goes to a controlled release. Observe watches it in production. Feed Back returns what production teaches to Define.
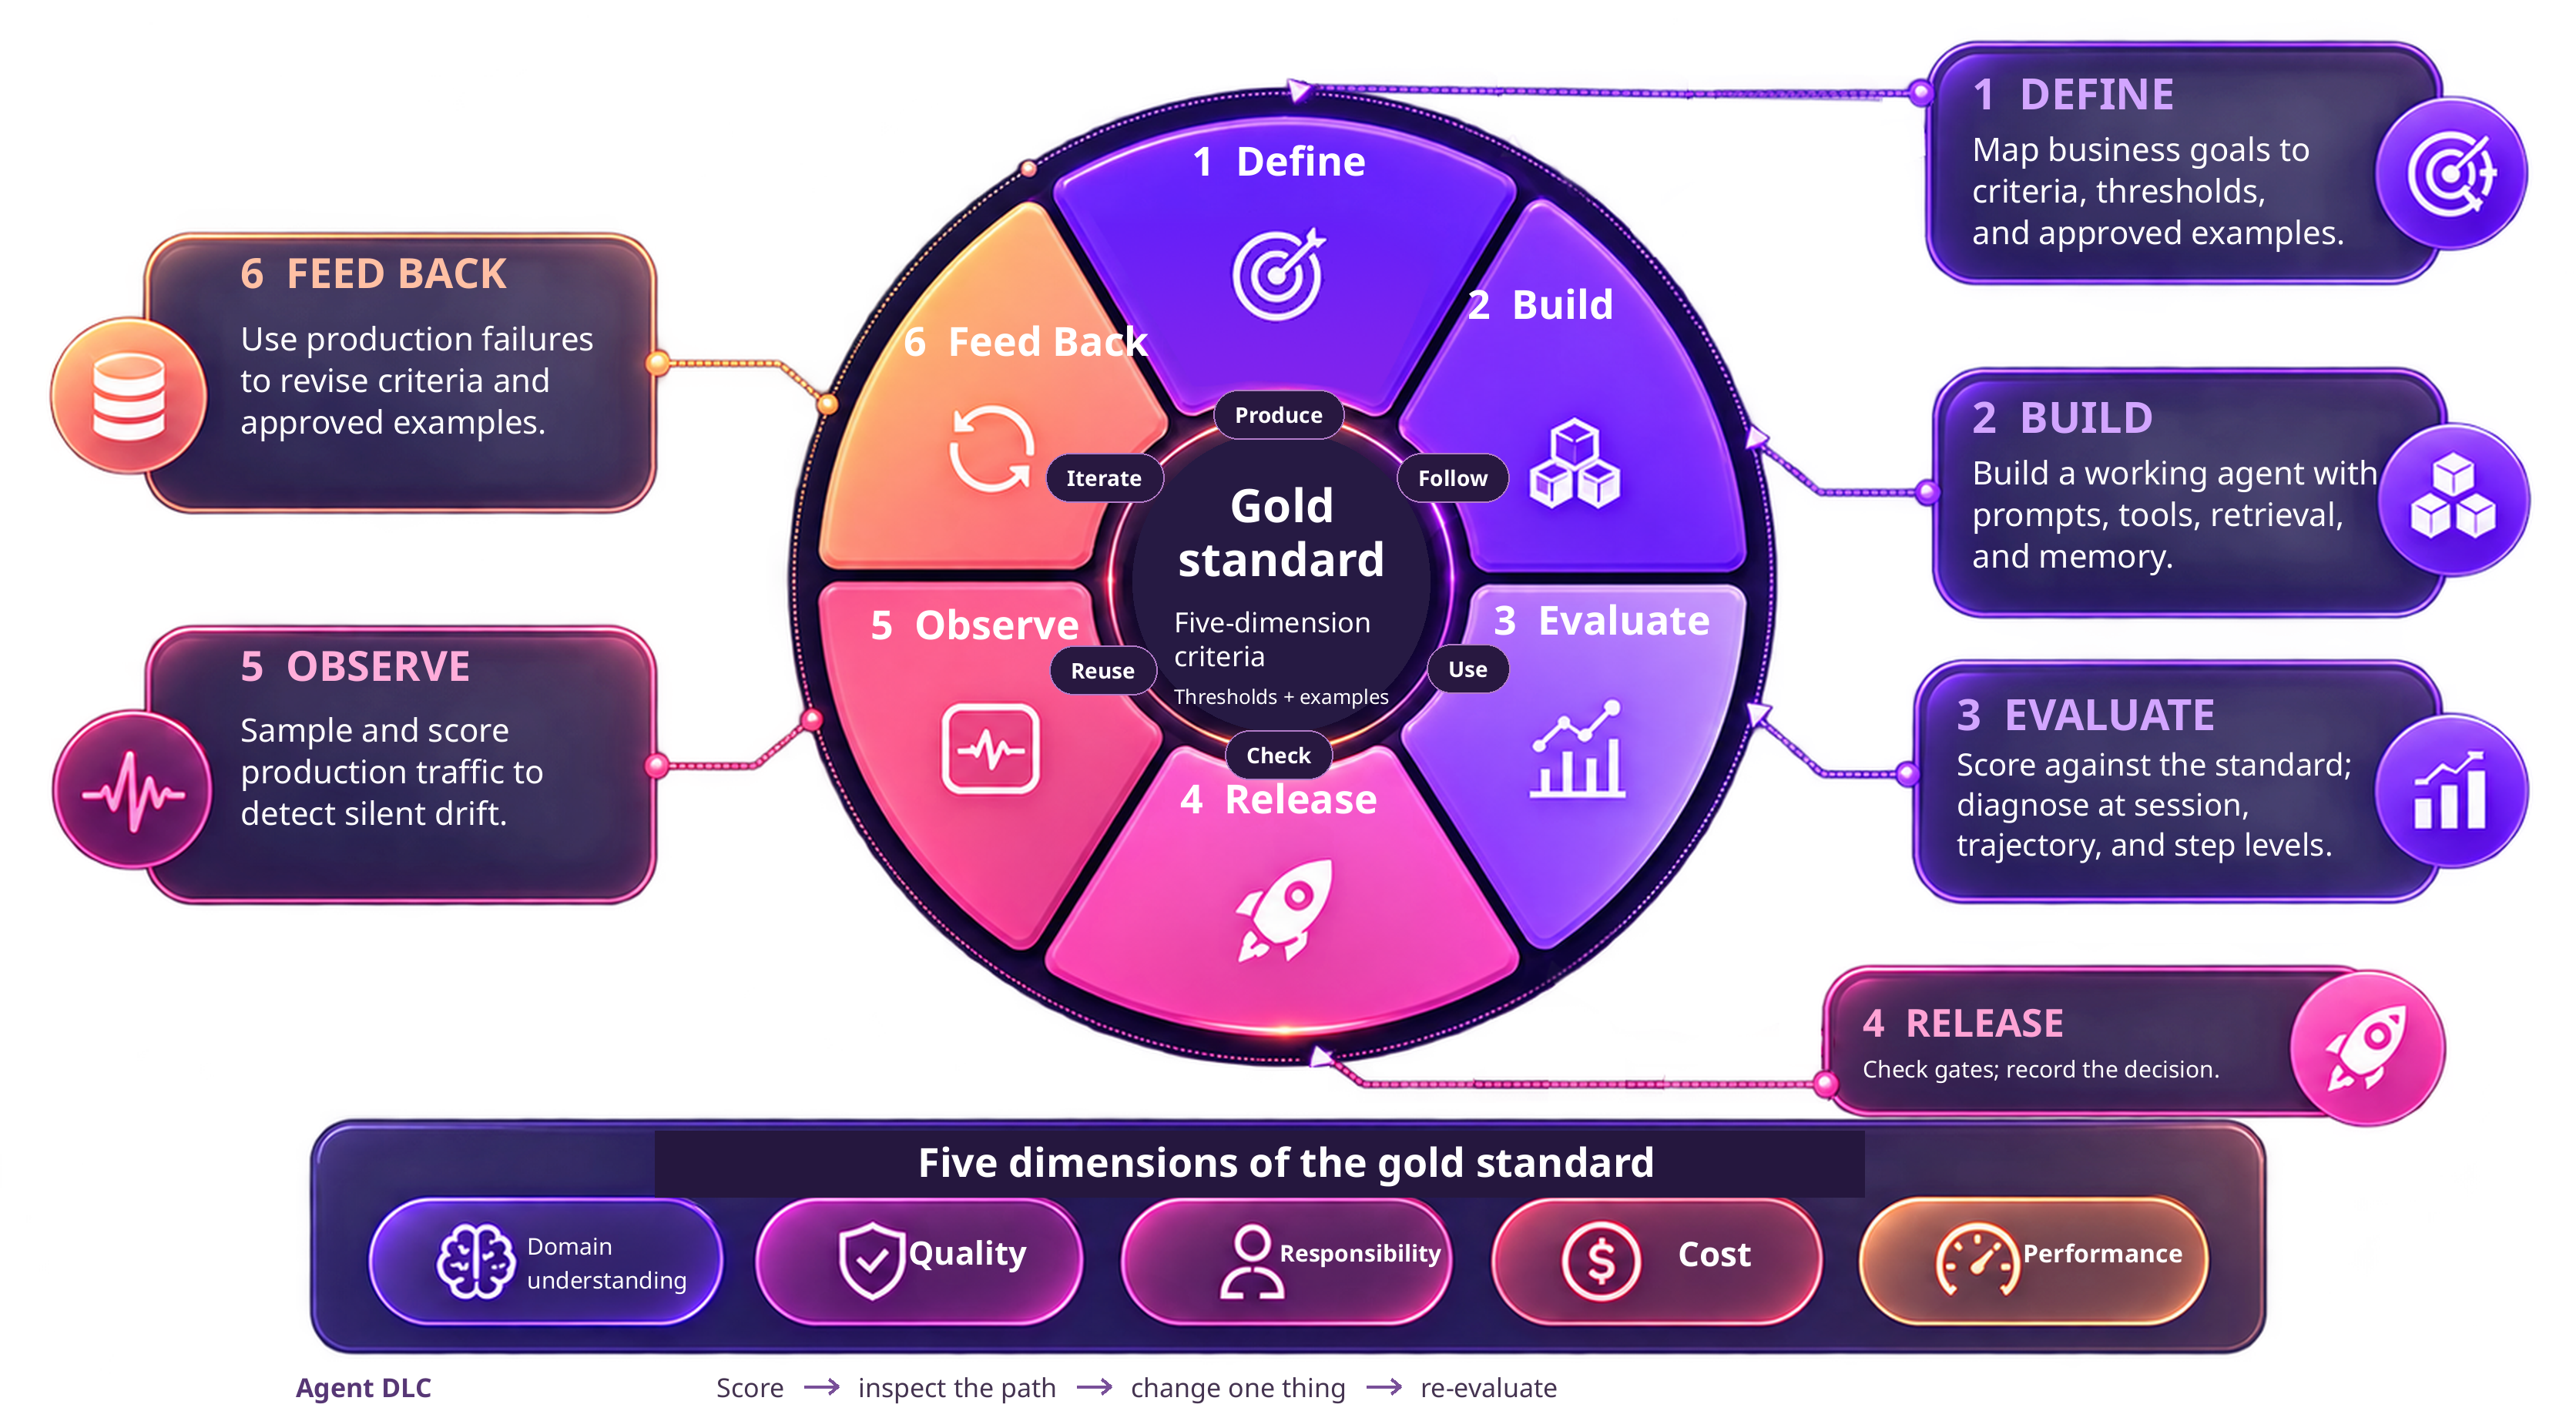
Figure 1: The six activities of Agent DLC each relate to the gold standard at the center. Define produces it, Build follows it, and Evaluate uses it. Release checks against it, Observe reuses it, and Feed Back iterates it. The five dimensions of the standard are listed beneath
Figure 1 shows how each activity uses or updates the standard, making its role in development and release explicit.
Inside that outer loop runs a faster inner loop: score → inspect the path → change one thing → re-evaluate. It operates on one candidate version and answers two questions: where to change, and whether the change helped.
The two loops do different jobs, and the difference matters. The inner loop improves the agent against a fixed standard. The outer loop lets the standard change. Finding during development that the agent recommends products without checking inventory is an inner-loop problem. Suppose production users ask the agent to look things up on behalf of a family member, but no criterion covers this case. This requires the outer loop: define the authorization boundary and add examples. Then use the inner loop to meet the updated standard.
Confusing the two can lead teams to try to fix a missing criterion with a prompt change. Teams might also widen the standard during an improvement cycle, leaving them unable to tell which change moved the score.
Both loops build reusable assets: business criteria, approved examples, evaluators, and the record of how past failures were handled. These assets outlive the model and the framework. When you change models, evaluate the replacement against the same criteria and examples.
The next four sections explain how to define good so it can be checked (section 4) and improve the agent against that standard (section 5). They then cover updating the standard through production feedback (section 6) and designing the architecture to provide evaluation evidence (section 7).
4. Define good: Five dimensions, three tiers
Start with a business outcome defined by its owner. For a recommendation agent, this might be: “Recommend suitable products to returning customers while protecting their information.” Translate that requirement into verifiable criteria across five dimensions.
Table 4. Consider all five dimensions when defining criteria.
| Dimension | Key question | Areas of focus |
| Domain understanding | Does it actually understand your business? | Terminology, aliases, multi-hop relationships, internal enterprise knowledge |
| Quality | Is it correct, complete, and consistent throughout? | Correctness, completeness, consistency, support for citations |
| Responsibility | Are permissions, boundaries, compliance, and auditability addressed? | Unauthorized access, information disclosure, compliance hard constraints, traceability |
| Cost | What does each run cost, and does it stay economical at scale? | Token consumption, evaluator cost, redundant steps |
| Performance | Is it fast, stable, and able to carry the load? | Latency, throughput, stability, availability |
For each criterion, specify how it’s verified and who approves it. “It must be accurate” is a goal. “Every factual claim must be traceable to a retrieved source” is verifiable. Business experts should approve examples that make the expected behavior concrete.
Table 5. Criteria fall into three tiers. The tier, not the dimension, decides whether a criterion blocks a release.
| Tier | Blocks release? | How it’s expressed | Example |
| Hard constraint | Yes | Boolean, evaluated per run | Disclosing another customer’s information |
| Release gate | Until it’s met | Pass-rate threshold over k runs | At least 95% of cited clauses traceable to a source |
| Monitoring only | No | Tracked and reviewed, promoted later | Tone appropriateness, until its evaluator is calibrated |
Assign each criterion its own tier and, where applicable, threshold. Never let a high score elsewhere offset a hard-constraint violation.
In the recommendation example, recommendation quality is a release gate under Quality, while protecting another customer’s information is a hard constraint under Responsibility. One business requirement produces criteria in different dimensions and tiers. Assess each against its own acceptance condition.
These criteria also determine what evidence the system must expose. The next section uses that evidence to improve the agent and decide whether to release it. Section 7 explains how evidence requirements shape the architecture.
5. The inner loop: Evaluate, diagnose, and improve
Score. Match the evaluator to the criterion. Use code for unambiguous rules, runtime telemetry for cost and latency, and load tests and operating data for capacity and availability. Use model-based judges for criteria requiring judgment, calibrated against human-reviewed examples. Include authorization and cross-user isolation tests alongside checks for prohibited fields when evaluating information protection. Run each example k times to assess variable behavior.
For model-based judges, repeat evaluations to measure scoring variability and compare their judgments with human-reviewed examples. Small score gains need supporting evidence before they count as improvements.
Inspect the path. Locate a failure at three levels: session, trajectory, and step. If a recommendation exposes a phone number, follow the affected session to response composition and inspect where profile fields entered the draft. The cause might be upstream of the visible symptom, as section 2 showed.
Change one thing, then re-evaluate. Correct the identified cause and repeat evaluation against the unchanged standard under the same conditions. Verify that disclosure stopped and recommendation quality still meets its gate.
Assess release readiness separately for each task type, or intent. Release only those that meet their criteria, with any fallback for an unreleased intent also meeting the agreed release conditions.
Table 6. Release decisions by dimension, tier, and intent.
| State of the grid | Decision |
| Any hard constraint failed | Don’t release. |
| All hard constraints pass, but one or more release gates missed | Don’t release the affected intent unless a limited rollout was approved in advance with explicit safeguards and stop criteria. Otherwise, route it to a human. |
| All hard constraints pass, and all release gates met | Full release. |
A limited rollout needs acceptance conditions, safeguards, and stop criteria agreed before evaluation. It can’t override a hard constraint or lower a threshold after a failed result.
Before release, include blocked and refused requests in the evaluation, checking whether each was handled as expected. Record the criteria, thresholds, evaluator versions, and release decision so the team can trace why a version was approved.
Passing these checks supports release within the tested scope. Production monitoring then checks whether the agent continues to meet the standard as usage and dependencies change.
6. The outer loop: Keep the data flowing
Record execution traces from the first test request so failures can be diagnosed in development and production. Sample and evaluate production interactions to identify failures, then review them with the business owner to confirm the expected behavior. Add cases covered by existing criteria to the regression set. When a case reveals a missing requirement, update the standard and use the inner loop to meet it.
Run evaluations regularly to catch behavior changes caused by external dependencies. When the standard changes, compare results under both versions to distinguish agent regression from broader test coverage. Link each result to its standard, test set, evaluator, and agent version.
7. Design the architecture to support evaluation
The evaluation and feedback loops need evidence that the architecture must provide. Work backward from each criterion to the system behavior and records needed to verify it.
For example, to distinguish a tool-selection error from an execution failure, define the tool’s purpose, accepted inputs, outputs, and error conditions. Expose the actual inputs, results, and errors in traces so evaluators can locate the failure.
Acceptance criteria therefore shape both evaluation and architecture. With those foundations in place, start with one business task and establish a baseline.
8. Getting started on AWS
Choose one clearly scoped business task and aim to establish an initial evaluation baseline within a week.
- Days 1–2. Have the business owner and engineers agree on acceptance criteria, tiers, and thresholds. Prepare 20–30 golden examples covering common requests and important edge cases, with expected behavior approved by the business owner.
- Days 3–5. Implement the evaluators described in section 5 and run the golden set repeatedly. Publish the baseline, including failures and the evidence needed to investigate them.
- Week 2. Change one thing and re-evaluate under the same conditions. Record the release decision and its supporting evidence.
After reviewing the baseline, integrate evaluation into the release process and run it regularly to detect drift. Assign an owner to review production failures and feed confirmed cases back into the standard.
On AWS, use models available through Amazon Bedrock to build the agent. Amazon Bedrock AgentCore Evaluations, a capability of Amazon Bedrock AgentCore, assesses agent behavior with built-in evaluators and supports custom evaluators for business-specific criteria. AgentCore Observability, a capability of Amazon Bedrock AgentCore, provides execution visibility, complemented by Amazon CloudWatch for runtime monitoring and diagnostics. AgentCore runtime, Gateway, Identity, and Memory support execution, tool integration, identity management, and memory management.