AI & ML
Learning Montezuma’s Revenge from a single demonstration
OpenAI Blog0 views
We’ve trained an agent to achieve a high score of 74,500 on Montezuma’s Revenge from a single human demonstration, better than any previously published result. Our algorithm is simple: the agent plays a sequence of games starting from carefully chosen states from the demonstration, and learns from them by optimizing the game score using PPO, the same reinforcement learning algorithm that underpins OpenAI Five.
Source:https://openai.com/index/learning-montezumas-revenge-from-a-single-demonstrationRelated posts
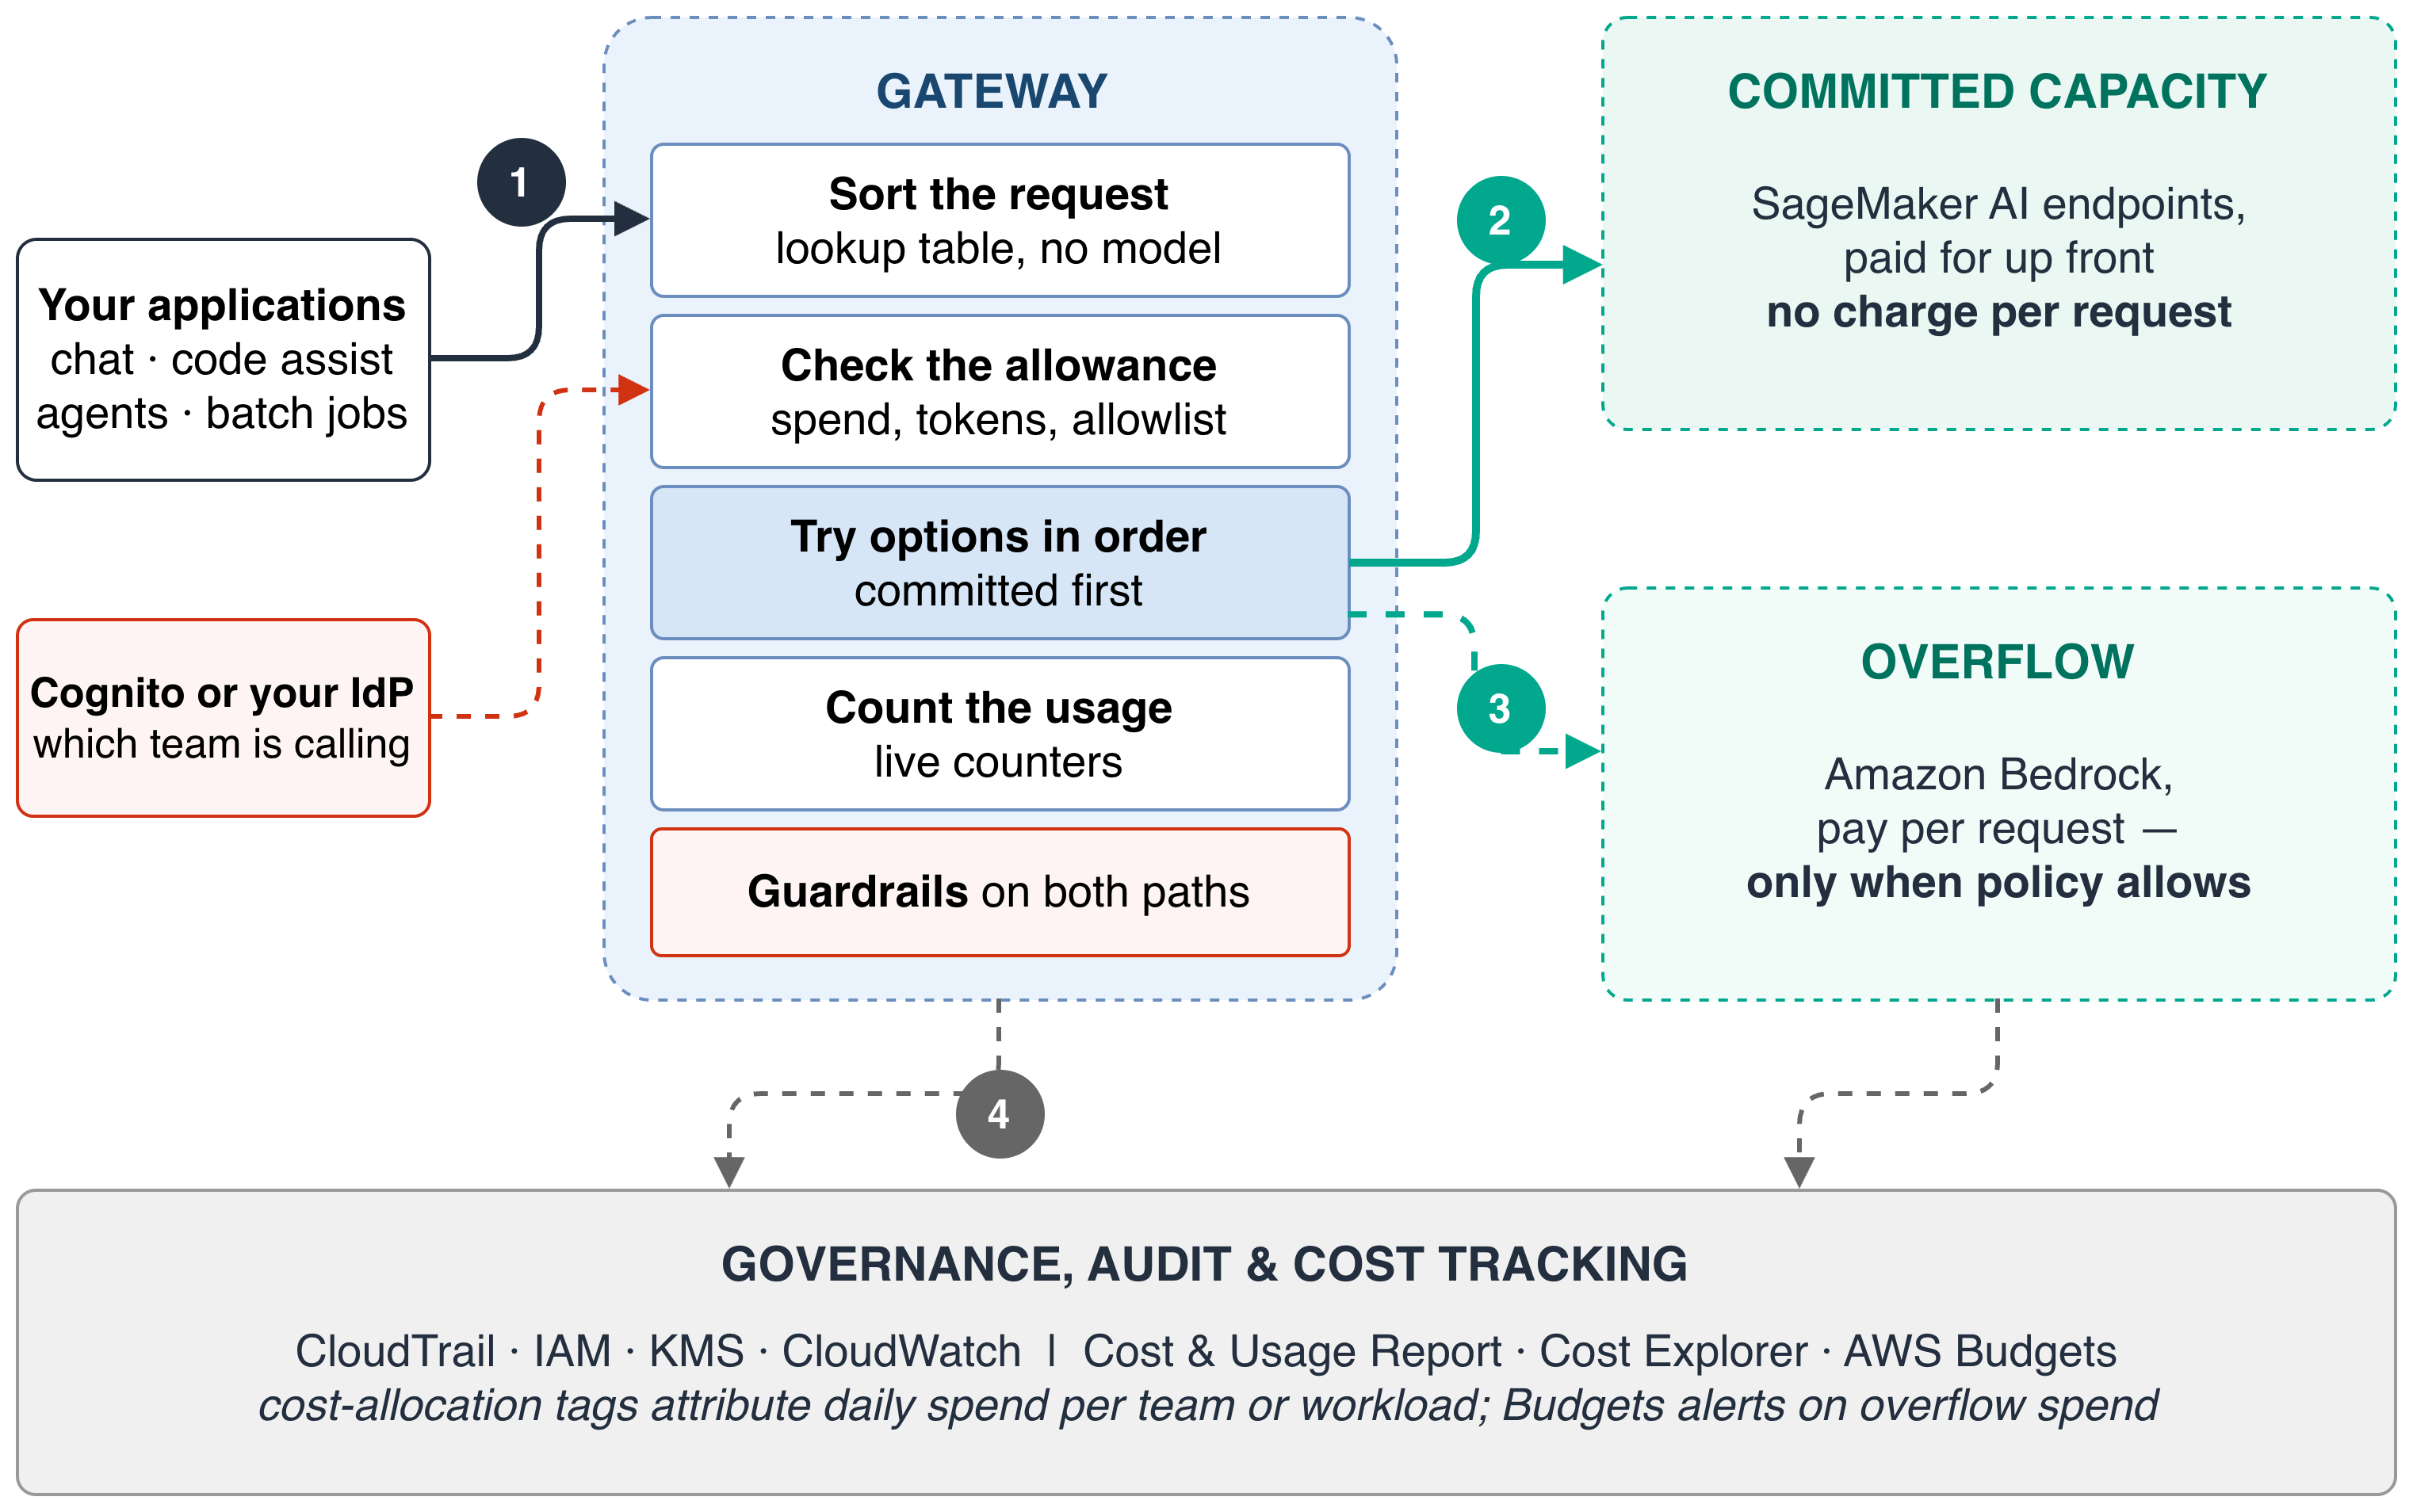
How and when to deliver AI at a fixed cost with AWS
0AWS Public Sector Blog
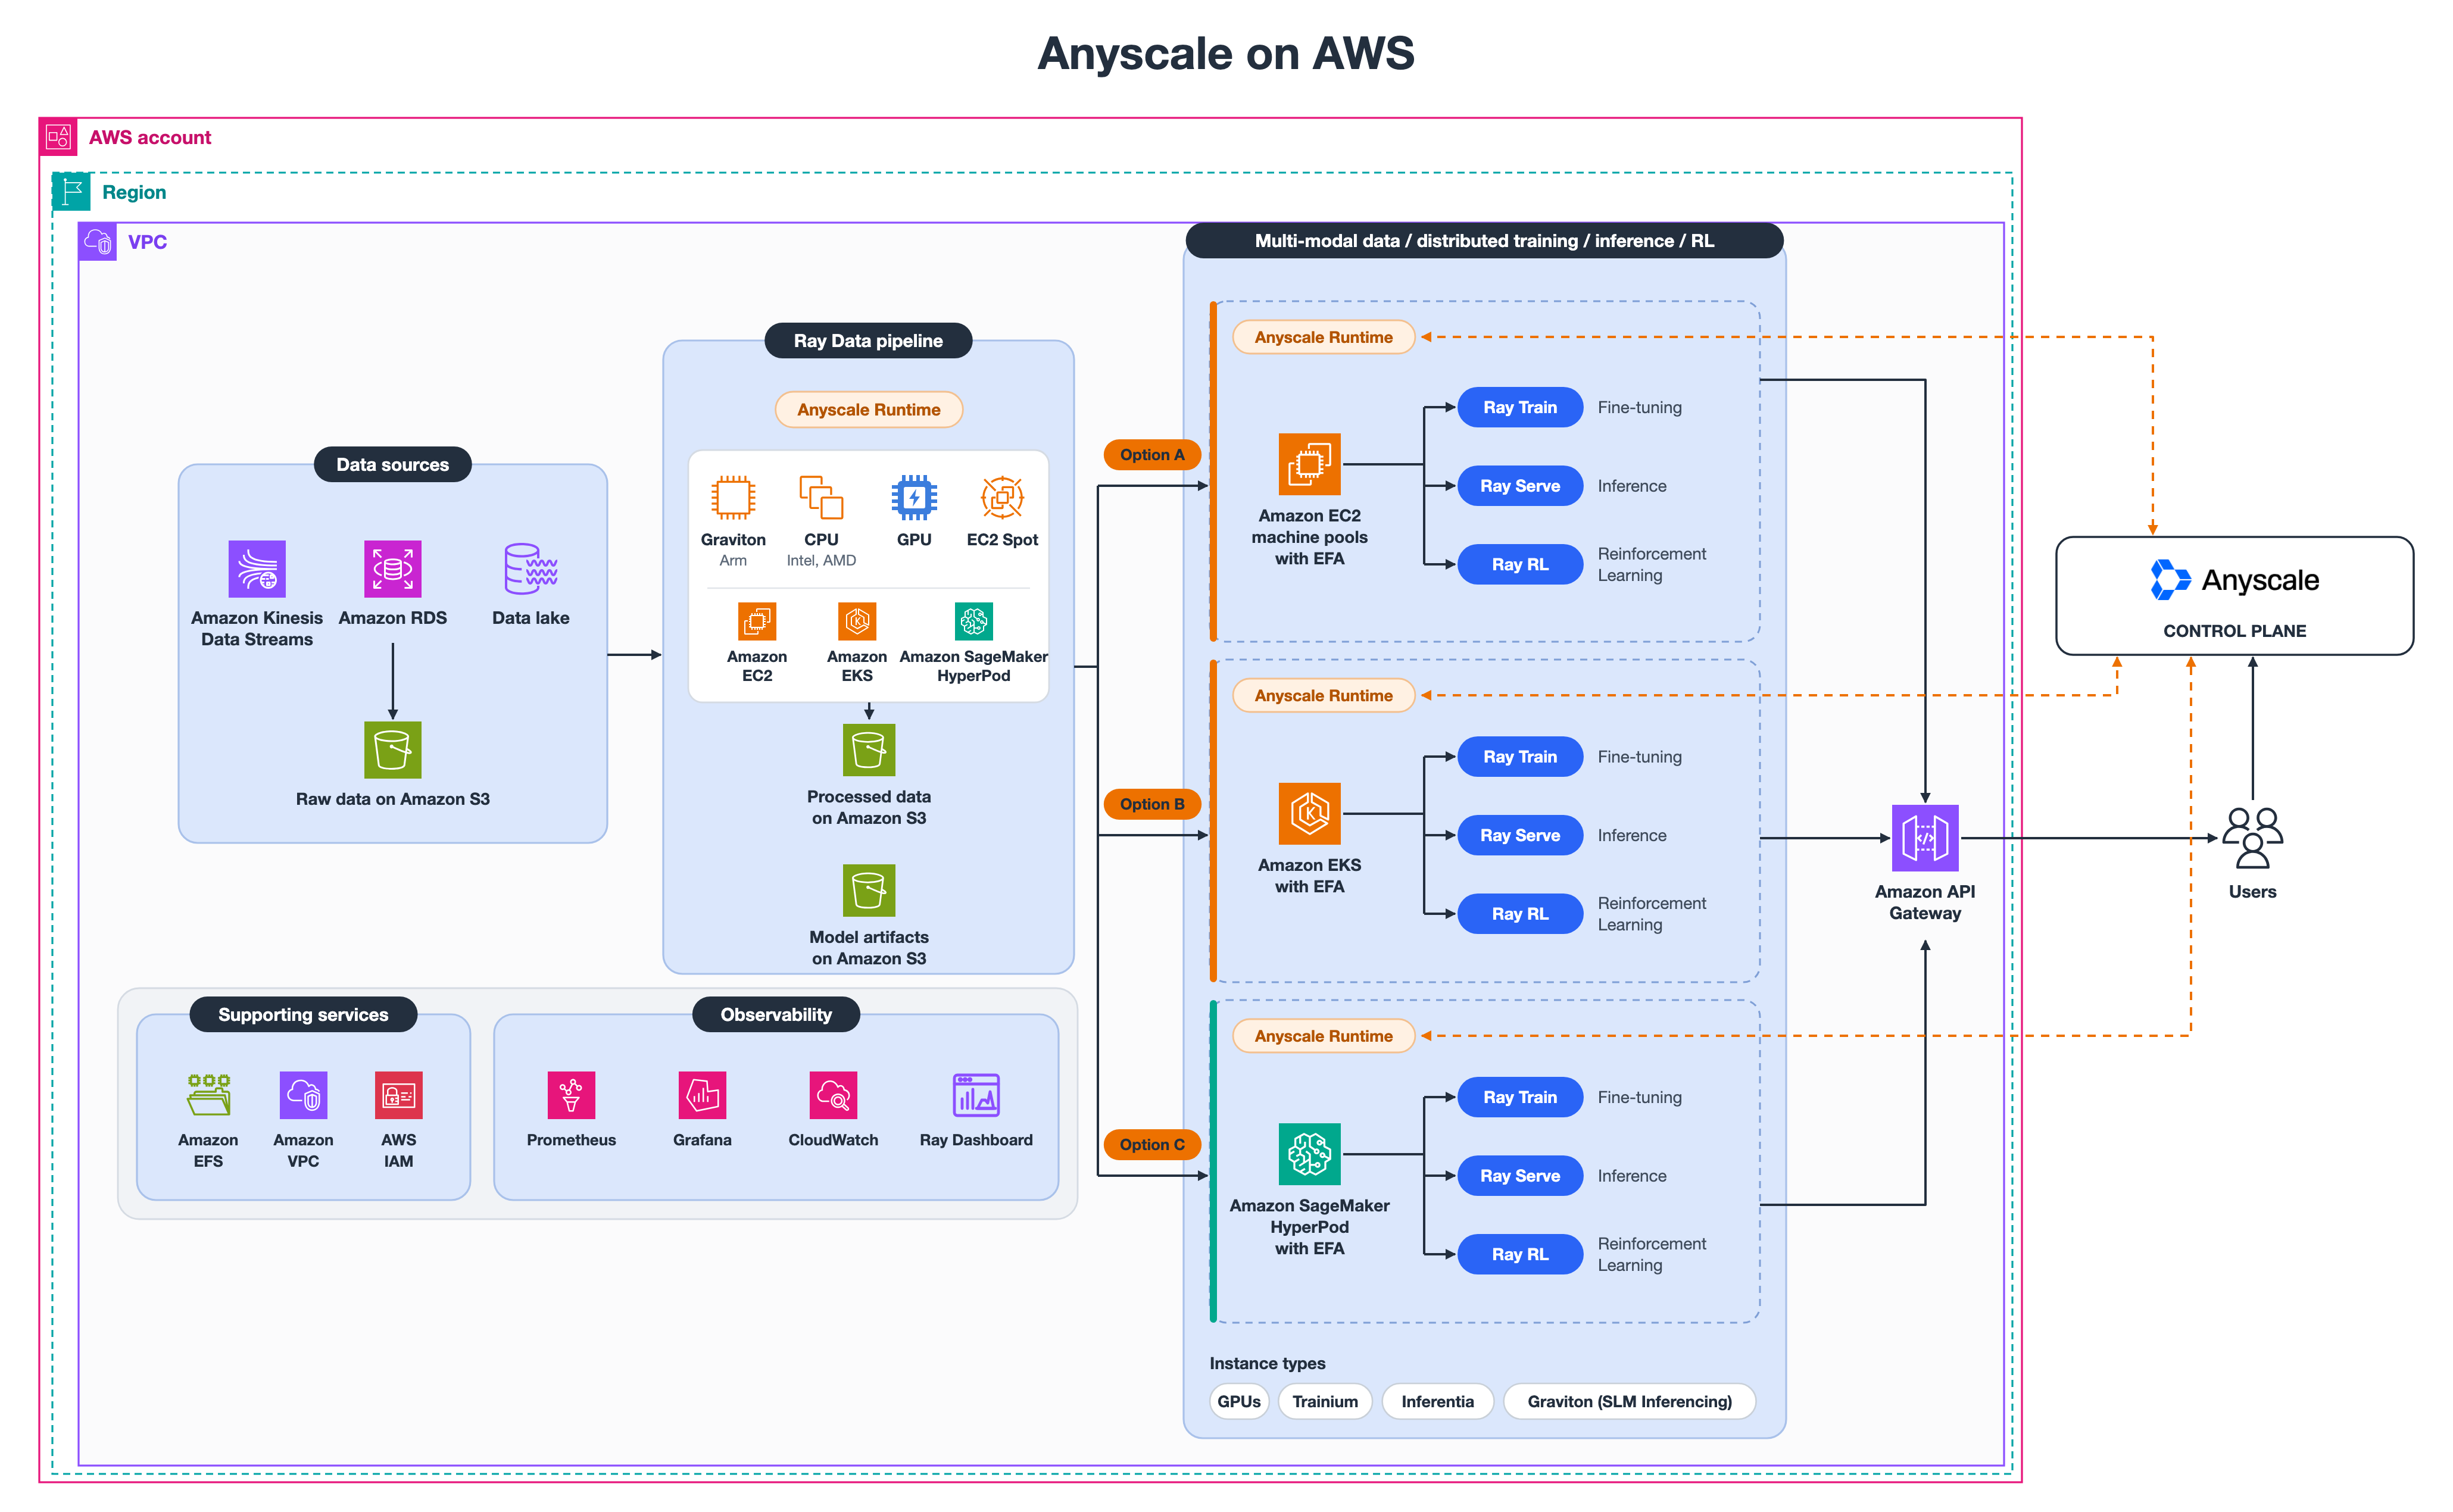
Scale distributed AI workloads with Ray and Anyscale on Amazon EC2
0AWS Architecture Blog
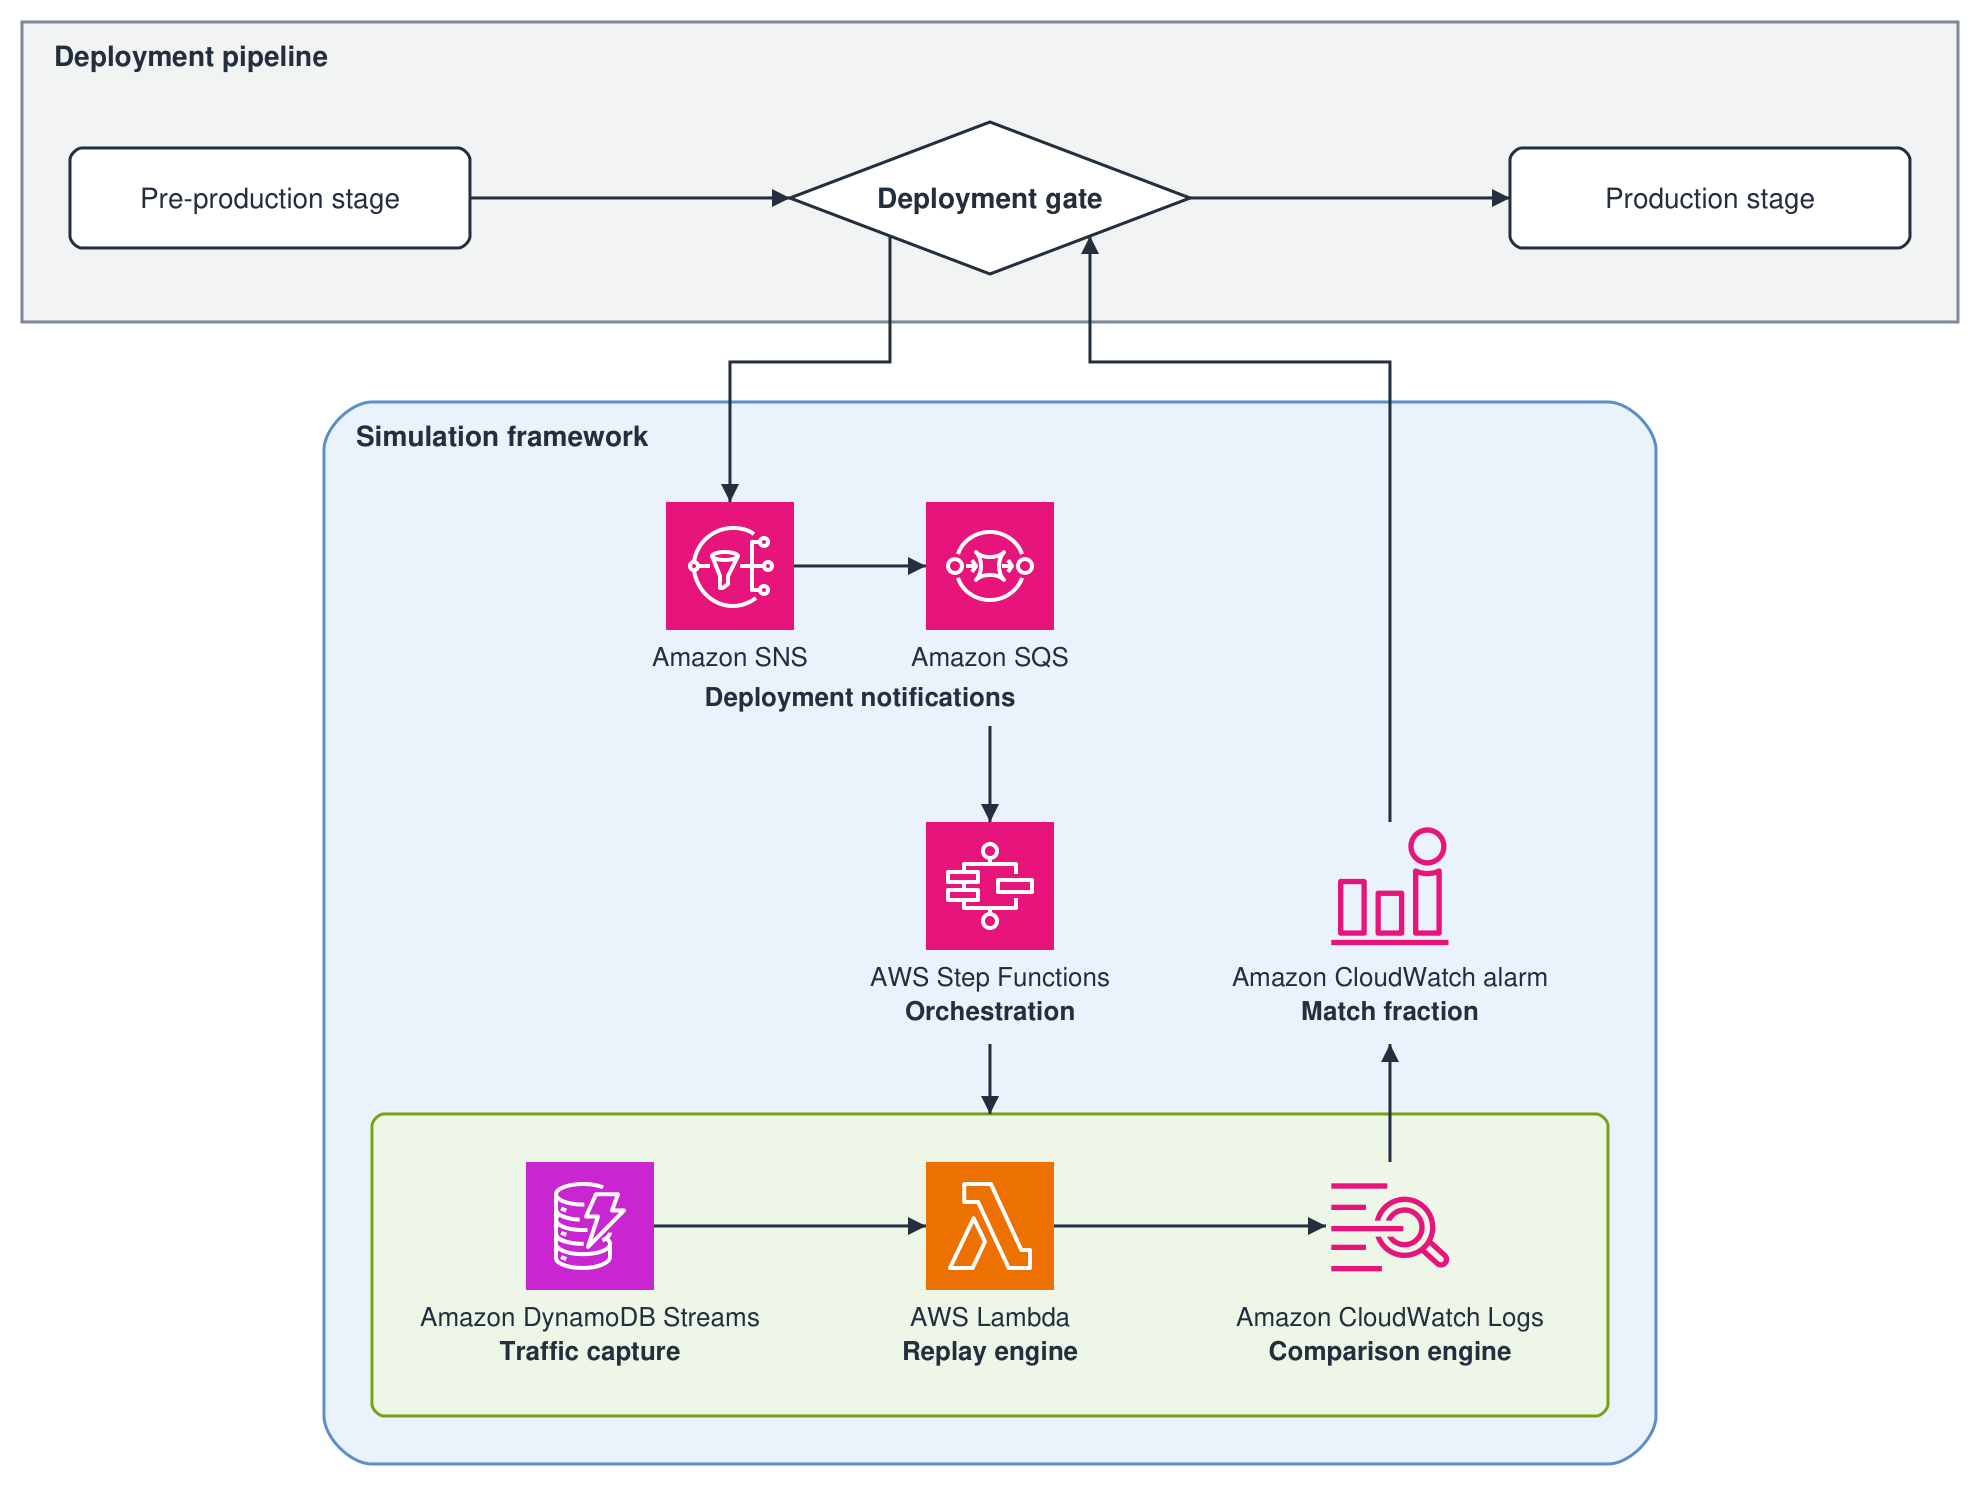
Modular regression testing framework built on AWS for large-scale systems
0AWS Architecture Blog

Google’s Gemini 4 coding agent now switches models mid-task — and finishes 19% faster
0The New Stack

Exploring faster language models suited to hardware implementation using reservoir computing
0Phys.org Tech

AI system can reconstruct aerodynamic shapes and predict their performance
0Phys.org Tech