AI & ML
Understanding Self-Supervised Representation Learning for Encrypted Traffic
arXiv cs.NI0 views
arXiv:2611.07452v1 Announce Type: new Abstract: SSL has been adopted for encrypted traffic classification to learn representations from unlabeled traces and reduce reliance on manual feature engineering. However, recent studies show that data leakage can inflate reported performance and that pretrained models can underperform shallow classifiers once leakage is controlled. These findings raise questions about what information SSL can learn from encrypted traffic and how different pretraining mechanisms exploit this information. In this paper, we systematically investigate these questions by examining the sources of learnable information, the effectiveness of contextual pretraining, alternative self-supervision mechanisms, and the limits of representation learning. We first find that visible protocol fields retain contextual dependencies that are strongest between adjacent bytes, while payload interventions establish the classification value of retained plaintext structure. Guided by these insights, we investigate byte-level contextual learning through ByteBERT and TrafficDCNet, showing that aligning prediction granularity with local dependencies produces more discriminative representations. We further examine cross-view contrastive learning through AlignTraffic and find that complementary supervision improves representation quality beyond contextual prediction alone. Across four public classification tasks, AlignTraffic outperforms shallow learning by 5.97% to 30.70%, with additional evaluations on industrial traffic demonstrating its effectiveness in broader settings. Finally, evaluations on Tor traffic and individual packets reveal limitations when application information is concealed or unevenly distributed. These findings provide a systematic understanding of how observable information and self-supervision mechanisms shape the effectiveness and scope of representation learning for encrypted traffic.
Source:https://arxiv.org/abs/2611.07452PreviousDeep reinforcement learning-based optimization of multi-RAT handoversNextWhen Does Blockwise Additivity Break? Diagnosing and Repairing the Additive Assumption in Distillation-Based Architecture Search
Related posts

Where an e-commerce explainer video belongs, and what to show in it
0dev.to

How to explain a crypto product on video without sounding like a pitch
0dev.to

Why Europe's Freezer Hacks Spread So Far, So Fast
0Dark Reading
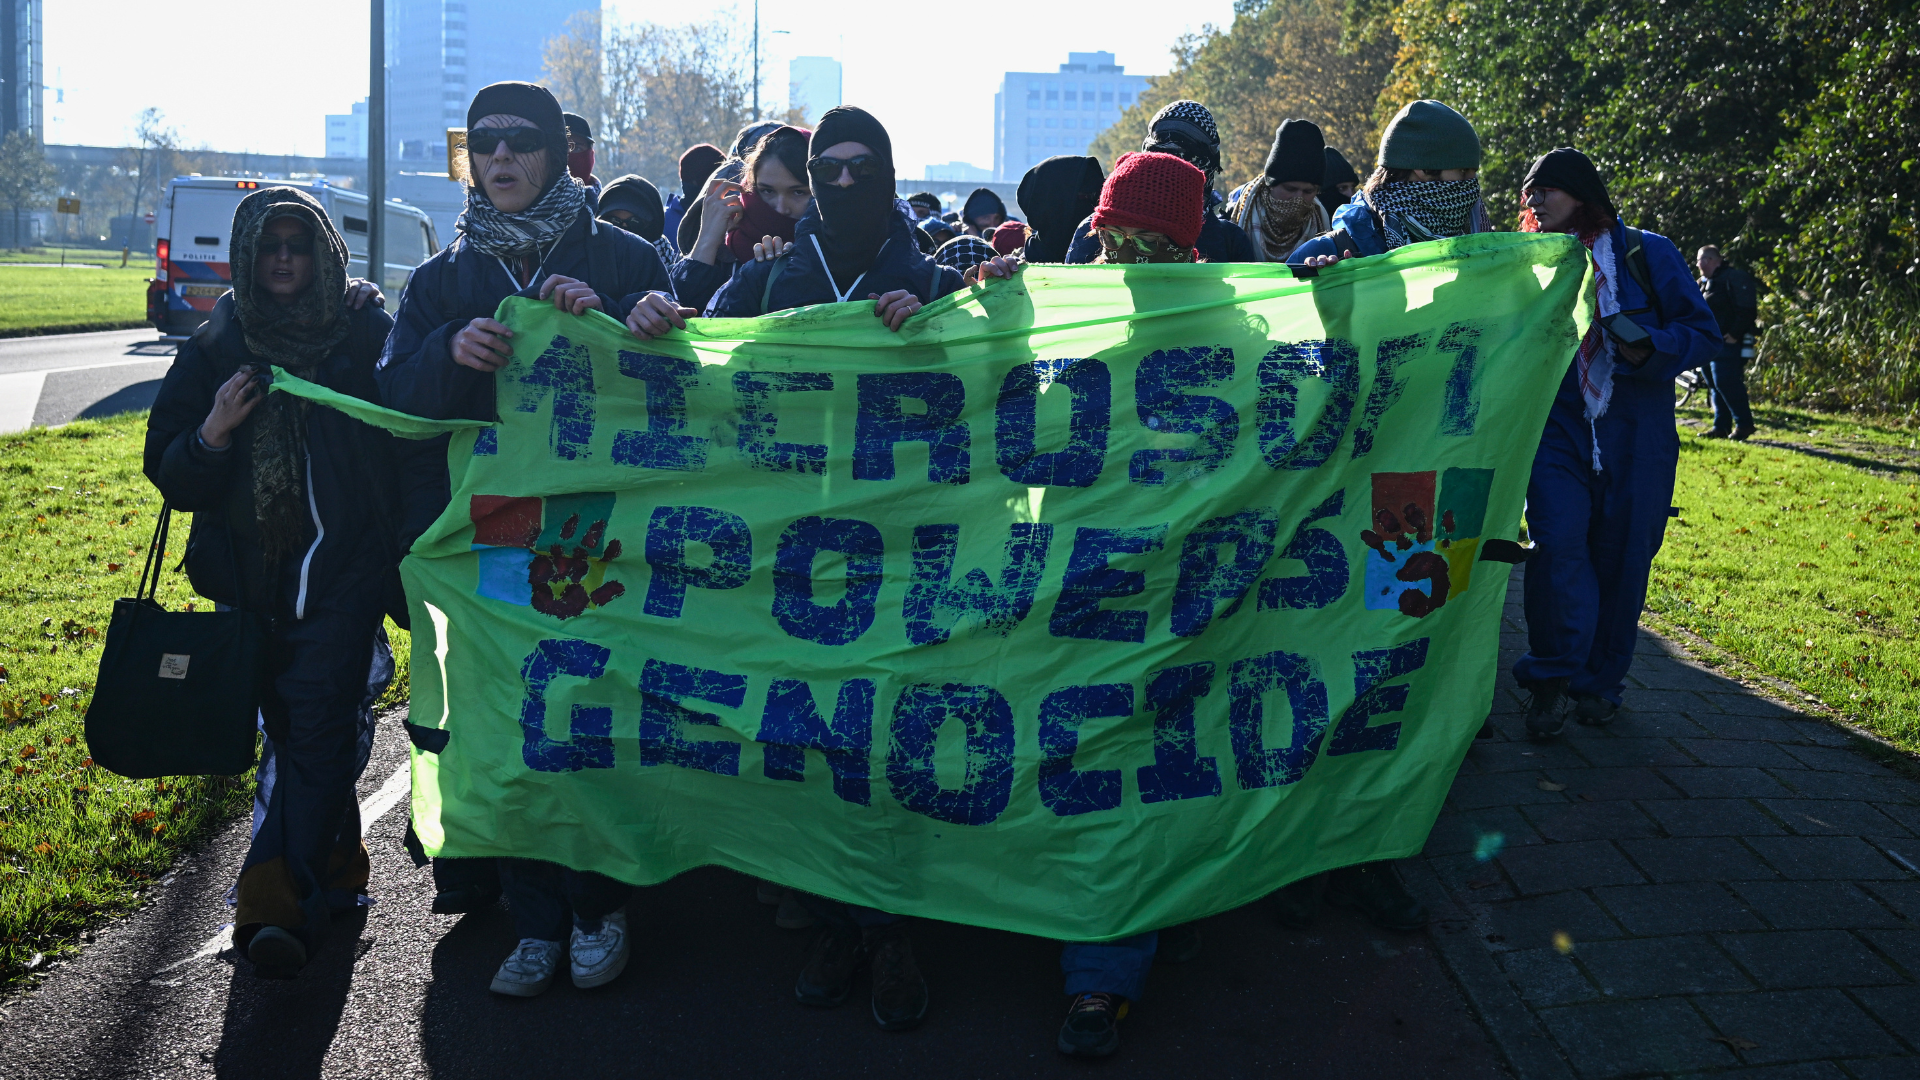
Protesters storm Microsoft AI data center construction site
0Tom's Hardware

The Download: a humanoid cleans house and Samsung builds for the AI boom
0MIT Technology Review

How Remedy designed Control Resonant’s wildest mission: ‘Anything kind of goes’
0The Verge