AI & ML
Matching Workloads to Blackwell: Power-Resolved Benchmarking of NVIDIA B200 and B300 across HPC and AI Workloads
arXiv cs.DC0 views
arXiv:2610.41919v1 Announce Type: new Abstract: We evaluate NVIDIA B200 and B300 (Blackwell Ultra) GPUs on two independent eight-GPU clusters, spanning computer-vision inference and training, LLM inference with Llama-3-8B and 70B~\cite{llama3}, and six production HPC codes. The B300 is not a uniform successor to the B200: it trails by up to 5.6$\times$ on convolutional inference, 8$\times$ on 3D vision transformer training, 24--27\% on 70B LLM throughput, and 16$\times$ on double-precision Quantum ESPRESSO. We resolve the convolutional deficit using per-GPU board power rather than throughput alone: on the affected workloads the B300 draws only 36--53\% of its 1100\,W envelope, whereas on ViT-Large, which it wins, both parts saturate at 95--97\% of TDP. Because our harness keeps inputs resident in device memory, a host-side data pipeline is excluded by construction, localizing the cause to per-kernel cost. Two B300 nodes of identical silicon differ by 2.1$\times$ in time-to-first-token solely from a development vLLM build. We give per-workload procurement guidance.
Source:https://arxiv.org/abs/2610.41919PreviousDecentralized Dynamic Stable MatchingNextAn Incentive-Aligned Trust-Centric Coordination Layer for Heterogeneous Blockchain Interoperability
Related posts
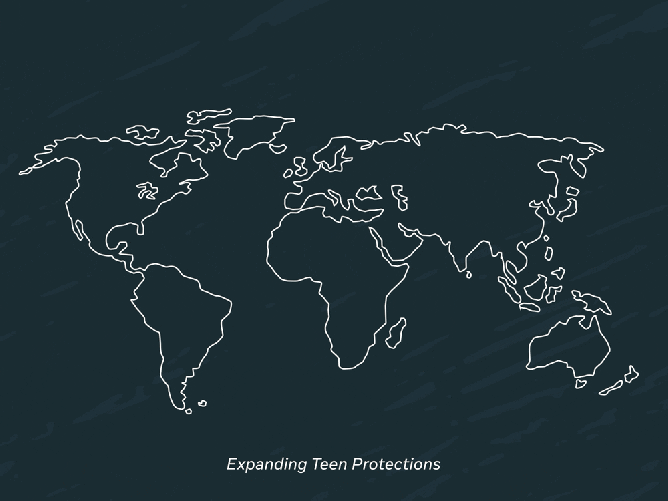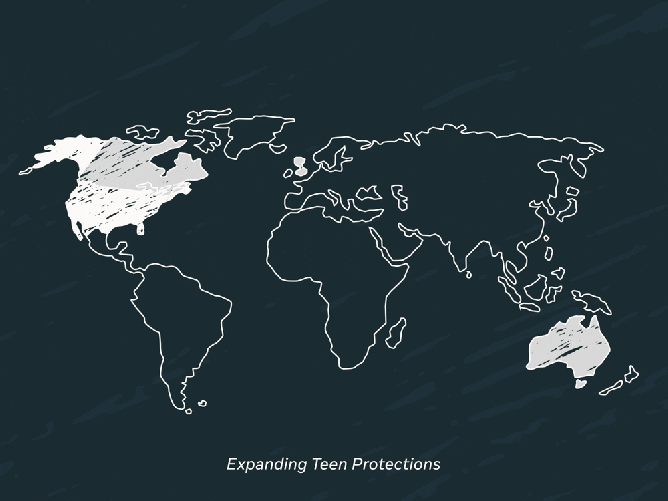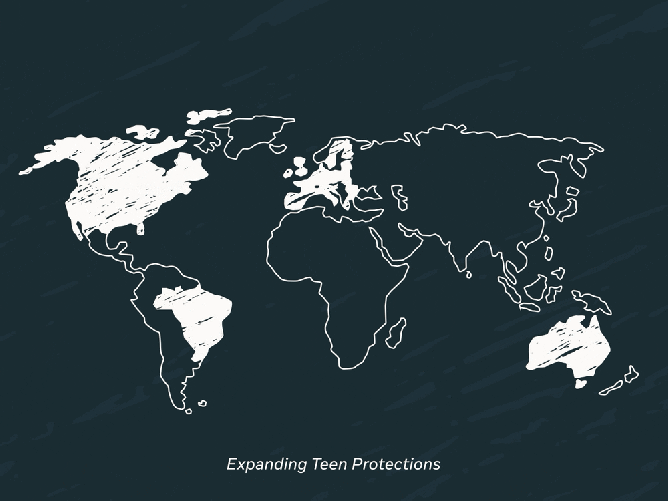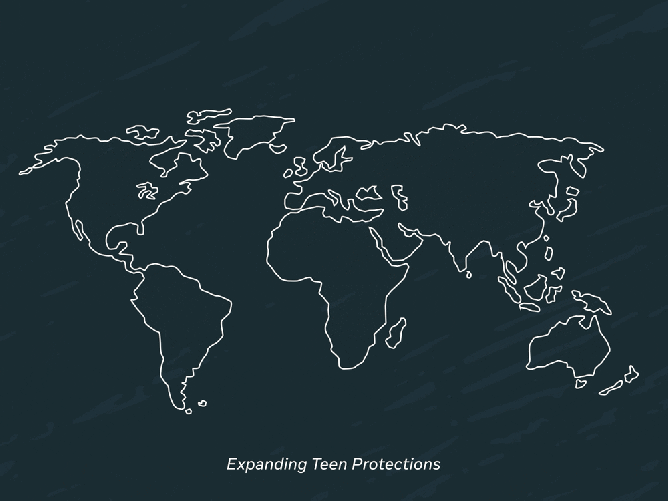
Expanding Teen Account Protections to Teens Around the World
0Meta Newsroom

Tối ưu hóa hiệu suất đầu ra: Tiền vệ Njie vực dậy hàng công Fiorentina với 5 lần in dấu giày
0dev.to Data

Hiệu suất săn bàn ấn tượng của Gouiri thúc đẩy chuỗi toàn thắng của Marseille
0dev.to Data

Hiệu suất săn bàn vượt trội của Kylian Mbappé trong màu áo Real Madrid
0dev.to Data

Hiệu suất toàn diện đưa Harry Kane vượt mặt Kylian Mbappe và Lamine Yamal trên bình diện thế giới
0dev.to Data

How Many .com Names Appear and Disappear Each Day?
0dev.to Data