General
Deliberative alignment: reasoning enables safer language models
OpenAI Blog0 views
Deliberative alignment: reasoning enables safer language models Introducing our new alignment strategy for o1 models, which are directly taught safety specifications and how to reason over them.
Source:https://openai.com/index/deliberative-alignmentPreviousWhy OpenAI’s structure must evolve to advance our missionNextOpenAI o1 and new tools for developers
Related posts

Musk, Uber co-founder join call for Jensen Huang's return to Nvidia
0Phys.org Tech
Grab a DDR5 gaming PC with a 10GB GPU for only $949
0Tom's Hardware

Physicists defy expectations by controlling the magnetic heart of a single atom
0Science Daily Tech

The secret to building Moon bases may be hiding in emergency blankets
0Science Daily Tech

Is the sixth great extinction imminent? Scientists must draw on natural history for clues
0Nature News
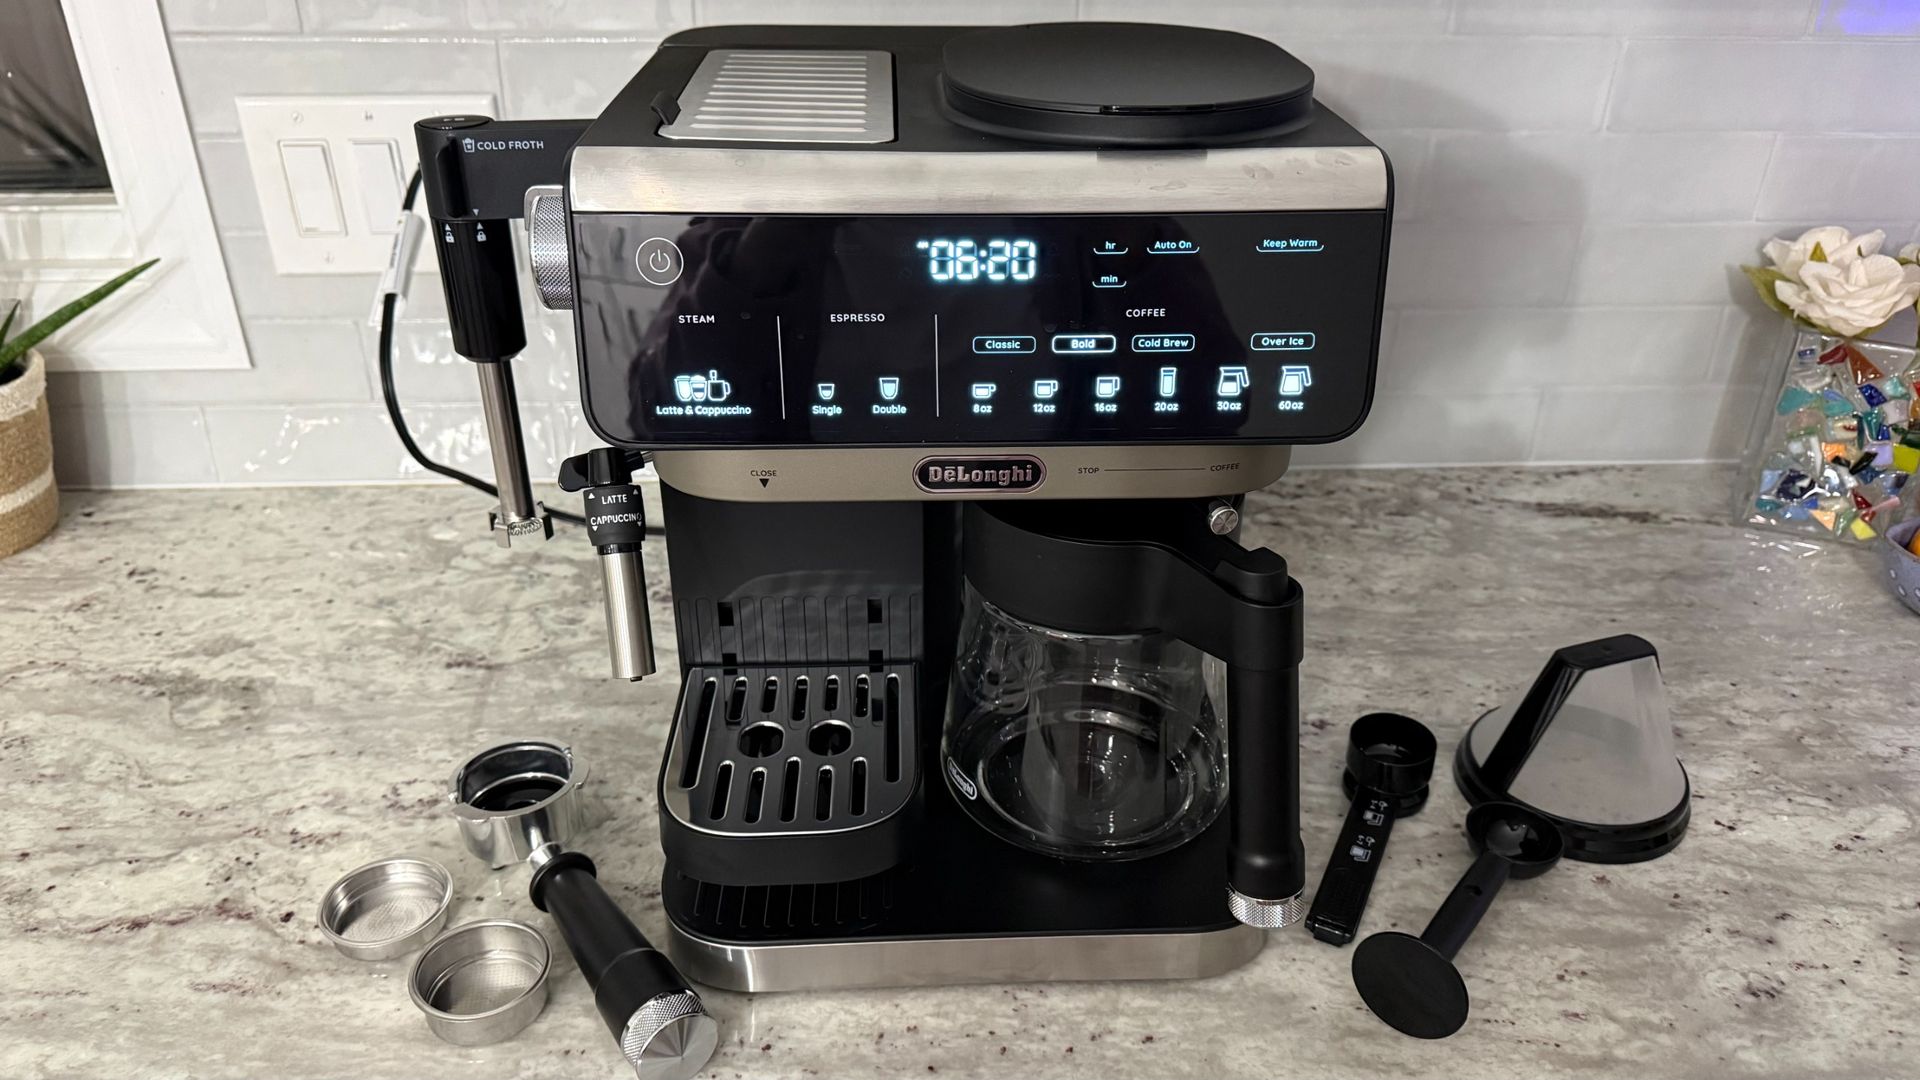
De’Longhi All-In-One review: one clever brewer for drip, espresso, and cold brew
0TechRadar