AI & ML
Location Matters: Layer-wise Prompt Conditioning for Voice--Style Disentanglement in Text-to-Speech
arXiv cs.SD0 views
arXiv:2611.24125v1 Announce Type: cross Abstract: Independent control of voice and emotional style characteristics of speech is a long-standing problem in text-to-speech (TTS) systems. We investigate how the conditioning location of voice and style prompts across TTS decoder layers affects the trade-off between preservation and expressiveness for voice identity and emotional style. We introduce a layer-dependent gated fusion mechanism and systematically study which layers should be influenced by which prompt type. Our findings show an asymmetric relationship. Voice benefits from early conditioning for identity preservation, while style benefits from early conditioning for expressiveness. Our findings provide practical guidance that helps neural network architects make an appropriate trade-off for the architecture of TTS systems according to their use cases.
Source:https://arxiv.org/abs/2611.24125Previous21Codec: Decoder-side Speaker Control for Text-to-SpeechNextWhy Multi-Source Audio Fails to Compose: A Geometric Diagnosis and Its Remedy
Related posts
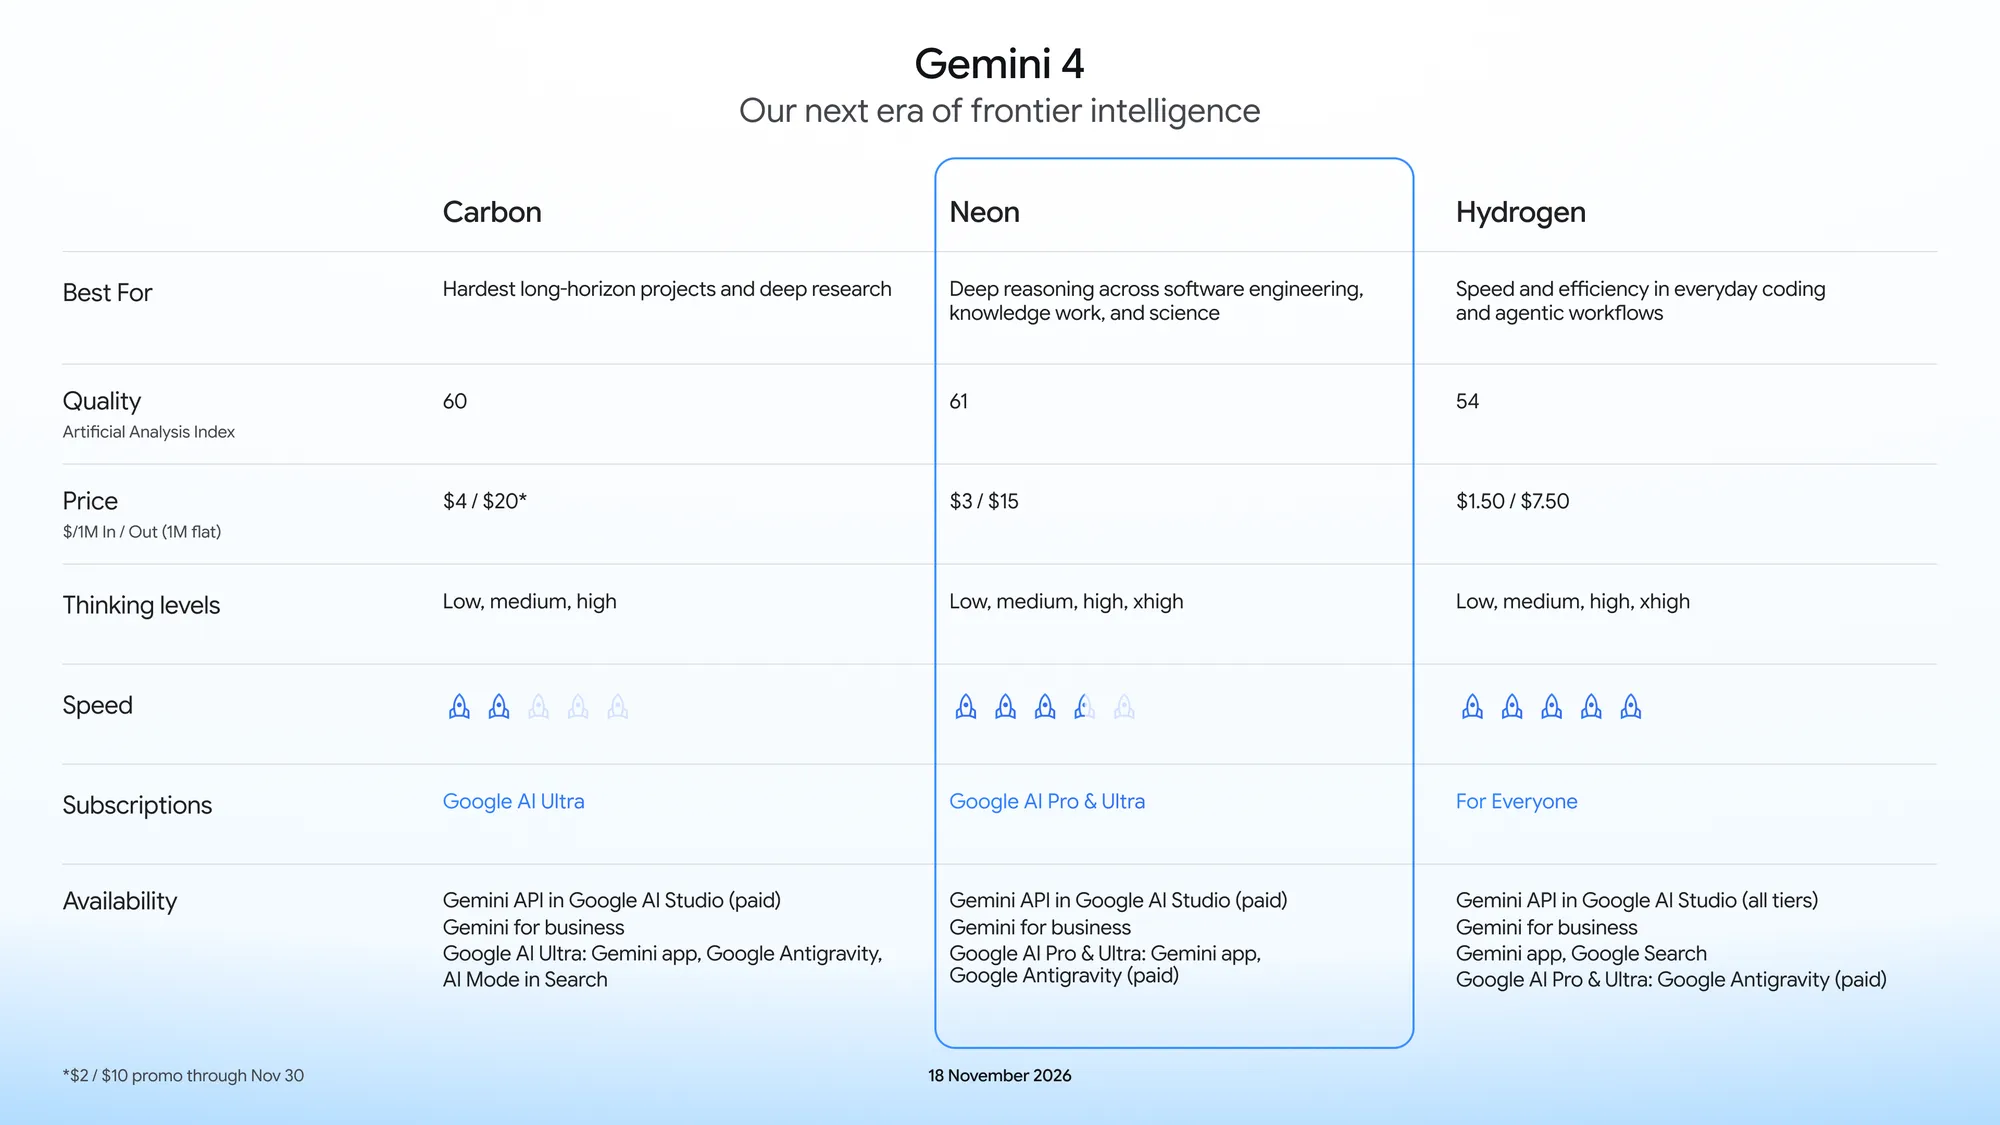
llm-gemini 0.38
0Simon Willison

How to detect user frustration in chatbot conversations
0dev.to

Mình Đã Biến Gemini Thành Trợ Lý Cá Nhân Như Thế Nào (Lịch, Drive, Gmail và Những Lần Suýt Toang)
0dev.to

Im looking fr any free ai models / tools are there?, leaVE UR Lights💡
0dev.to

I checked 10 SEO agency websites for AI-search readiness. The real bugs were the boring ones.
0dev.to

How much GPU memory does an LLM need? The whole sum, worked out on real cards
0dev.to