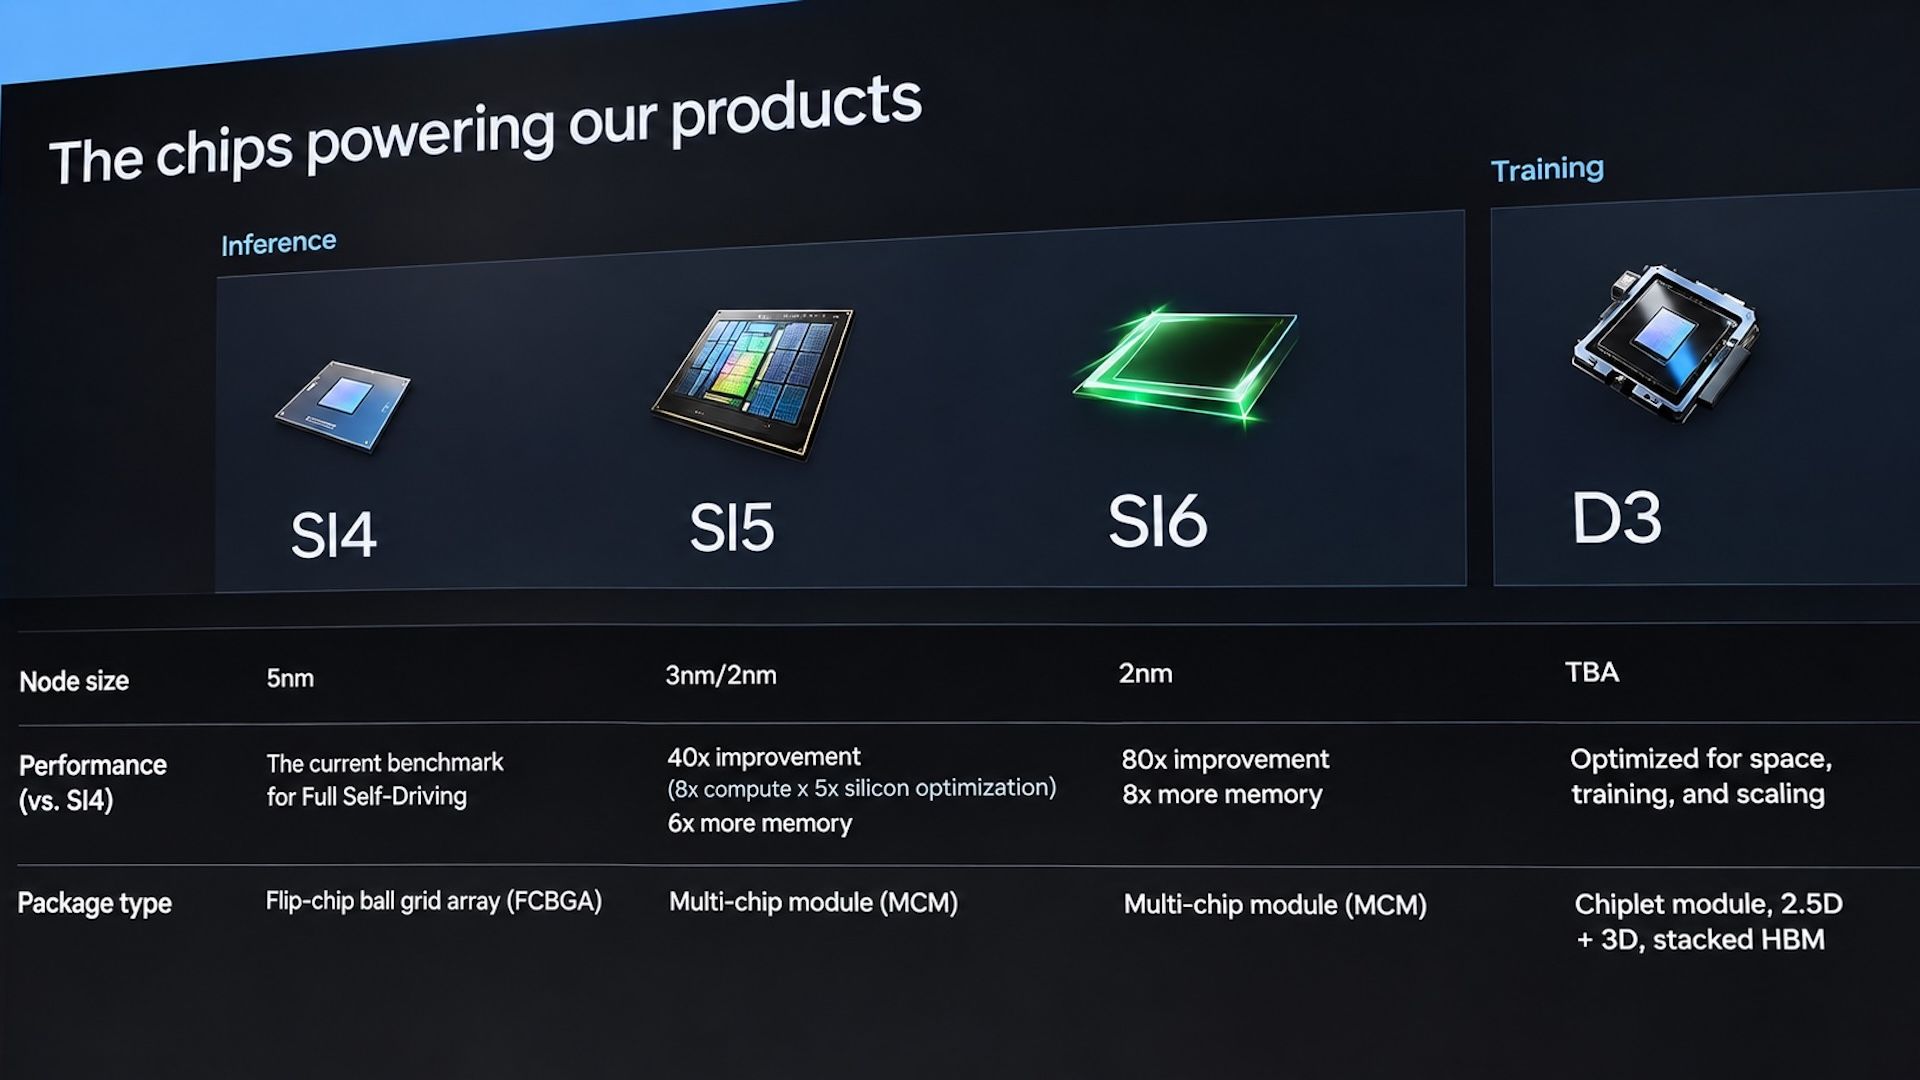
Tesla has disclosed its revamped AI accelerator roadmap that sheds some light on the future of the company's chip development efforts. The Elon Musk company expects that its 6th Generation inference accelerator will bring 80X more compute performance than the existing 4th Generation chip, whereas its D3 training accelerator will cease to use SRAM-centric architecture in favor of a multi-chiplet design with stacked HBM. Also, Tesla has adopted the term "super intelligence" instead of artificial intelligence for its AI accelerators, renaming them with SI monikers. Musk recently confirmed SpaceXAI would be redubbed SpaceXSI for the same reason.
Wait a minute… I thought @elonmusk ’s Tesla chips were called AI4, AI5, and AI6.But in this latest presentation, they’re now labeled SI4, SI5, and SI6.Then I remembered: President Trump wants to replace “Artificial Intelligence” (AI) with “Super Intelligence” (SI).Looks like Elon Musk may already be embracing the new terminology. 🤔November 4, 2026
HW3 | AI3 | SI4 | HW4 | SI5 | AI5 | SI6 | AI6 | Dojo D1 | Dojo D3 | |
Application | Inference | Inference | Inference | Inference | Training | Training |
Process technology | Samsung 14nm | Samsung 7nm | TSMC 3nm / Samsung 2nm | 2nm-class | TSMC 7nm | TBD |
Architecture | Monolithic | Monolithic | MCM | MCM | SoW | Chiplets |
Packaging | FCBGA | FCBGA | MCM | MCM | InFO_SoW (training tile) | 2.5D + 3D |
Memory type | LPDDR4 | GDDR6 | GDDR6/GDDR7 (?) | GDDR7 (?) | On-chip SRAM | Stacked HBM |
Memory capacity | 8 GB | 16 GB | 96 GB | 144 GB | 440 MB SRAM per die | TBD |
Memory bandwidth | ~68 GB/s | ~224 GB/s | TBD | TBD | ~10 TB/s (on-chip) | TBD |
Performance vs. SI4 | — | 1X | 40X | 80X | — | — |
Estimated compute (TOPS) | 72 TOPS | 216 – 576 | 8,640 – 23,040 | 17,280 – 46,080 | 362 TFLOPS | TBD |
Estimated compute (POPS) | 0.072 | 0.216 – 0.576 | 8.64 – 23.04 | 17.28 – 46.08 | 0.362 PFLOPS | TBD |
Status | Legacy | Production | Nearing Production | Development | Discontinued | Development |
Dojo D3: No more wafer-level integration?
Perhaps the most interesting development in Tesla's AI hardware roadmap is the re-emergence of the in-house developed Dojo training accelerator after Elon Musk cancelled the whole wafer-level Dojo project in August, 2025, and then said SpaceX and xAI would exclusively use Nvidia hardware in August, 2026, both in its terrestrial and extraterrestrial data centers. Yet, the 3rd Generation Dojo will be considerably different from the first two generations, Dojo D1 and Dojo D2.
Tesla describes its next-generation Dojo 3 (D3) training accelerator as a chiplet-based design that combines 2.5D and 3D packaging technologies with stacked HBM. This represents a substantial departure from the original Dojo D1 system-on-wafer architecture, which relied on distributed on-chip SRAM and interconnected 25 D1 processors with 11 GB of SRAM using wafer-scale packaging technology. The adoption of HBM suggests that Tesla intends to substantially increase memory capacity, as modern AI models consume extreme amounts of memory to store parameters, activations, and intermediate data, making SRAM unattractive from a capacity standpoint. The use of HBM simplifies memory scaling but introduces different latency, bandwidth, packaging, and power trade-offs. Yet, it remains unclear whether the company has abandoned wafer-scale integration altogether.
On the one hand, it is possible to stack custom HBM modules on top of logic dies interconnected using wafer-scale packaging technology. On the other hand, wafer-level integration is expensive and makes the most sense for select use cases, which include SRAM-centric architectures. Stacking HBM atop wafer-scale interconnected logic dies adds further design complexities, cooling challenges, manufacturing complexity (i.e., potentially reducing yields), long-term reliability concerns, and ultimately costs. While most of the challenges can be resolved by adding redundancy and refining process technologies, this all comes at a cost, making wafer-scaling less likely for D3.
Tesla has yet to disclose D3's compute performance, memory capacity, manufacturing process, or development schedule. At the same time, it claims that its Dojo D3 will be optimized for 'space, training, and scaling,' which means the unit will offer decent performance and will be easy to scale (which again points to a more conventional architecture of accelerators rather than to wafer-scale packaging). More intriguingly, the D3 is also set to be optimized for extraterrestrial deployments, which probably means radiation hardening for at least select SKUs.
SI6: 80X more performance than HW4 in a few years
Another interesting detail in the roadmap is the disclosure of approximate compute performance of Tesla's 6th Generation inference accelerator (SI6): 80X compute improvement over HW4 and 9X more memory over HW4. Depending on how HW4 performance is measured (read on for explanation), we are talking about 17,280 – 46,080 TOPS (trillion operations per second), or 17.28 – 46.08 POPS (quadrillion operations per second), though we do not know anything about data formats supported by SI6. Of course, these are estimates, so take them with a grain of salt. To put the numbers into context, Nvidia's Rubin GPU offers 50 NVFP4 PFLOPS for inference, 35 NVFP4 PFLOPS for training, and 17.5 FP8/FP6 PFLOPS. Meanwhile, Rubin is shipping to customers today, whereas SI6 is due in 2029 – 2030. There are some additional details about SI6, which we will discuss below.
Tesla's existing 4th Generation inference processor used in the company's automobiles today (which was originally called HW4, then renamed to AI4, then to SI4) is made by Samsung Foundry using its 7nm-class process technology and relies on conventional flip-chip ball grid array (FCBGA) packaging (note that the alleged Tesla slide contains a mistake and claims that the unit is made using a 5nm-class node) as well as presumably 16 GB of GDDR6 memory. The company describes the processor as the current benchmark for its Full Self-Driving (FSD) technology, which makes it the baseline against which performance of future generations is measured. Meanwhile, Tesla does not officially disclose the chip's absolute compute performance numbers, memory capacity, or power consumption, which makes comparison hard. Elon Musk once said that HW4 is 3X – 8X more powerful than HW3, which was officially rated at 72 TOPS, making HW4 a 216 – 576 TOPS ASIC (note that these are estimates).
As expected, the slide re-confirms that the upcoming 5th Generation inference accelerator called SI5 (aka HW5 aka AI5) will be manufactured using 3nm- and 2nm-class process technologies at TSMC and Samsung Foundry, respectively, and will adopt a multi-chip module (MCM) design, marking a departure from the conventional packaging approach used for HW4. Tesla expects SI5 to deliver a 40X performance improvement over HW4, which will be a result of an eightfold increase in compute capabilities (driven by considerably denser process technologies and more execution units) and a fivefold gain from silicon optimization, according to Elon Musk, which points to 8,640 – 23,040 TOPS (an estimated figure), depending on how one counts performance of HW4. Meanwhile, the processor is expected to consume from 250W to 800W depending on application, so making performance estimates at this point is not exactly a good business. Meanwhile, the processor will also feature six times more memory than its predecessor (i.e., 96 GB). Depending on the memory type used (GDDR6 or GDDR7), the Tesla SI5 can offer memory bandwidth between 768 GB/s and 1.536 GB/s.
Moving on to the Tesla's 6th Generation inference accelerator (SI6), which is set to further increase compute performance to 80 times that of HW4 and feature eight times more memory than the current-generation processor. This could translate to 17.28 – 46.08 POPS (quadrillion operations per second), depending on how to count HW4 performance, and 144 GB of memory, which is significant performance and amount of memory for an AI accelerator.
Tesla has already inked a deal with Samsung Foundry to make its 6th Generation inference accelerators through 2033, and the new slide reveals that the unit will be made using a 2nm-class process technology. Given the fact that the chip is due in 2029 – 2030 and Samsung's recently updated foundry roadmap, we are probably talking about automotive-grade SF2A, performance-enhanced SF2P, or even SF2Z with backside power delivery. Meanwhile, a thing that strikes the eye with the SI6 is that Tesla does not envision the chip to be produced at Terafab using Intel's 14A fabrication process in the 2030s.
SI6 will retain the multi-chip module (MCM) approach introduced with AI5/SI5/HW5, which seems rational as it will be able to leverage experience it is going to get with its 5th Generation inference accelerator and retain relatively reasonable packaging costs. Many automakers are considering adoption of multi-chiplet designs and HBM memory for their next-generation system-in-packages (SiPs), which will drive their costs. It remains to be seen when Tesla adopts HBM for its inference accelerators, but probably not with SI6.