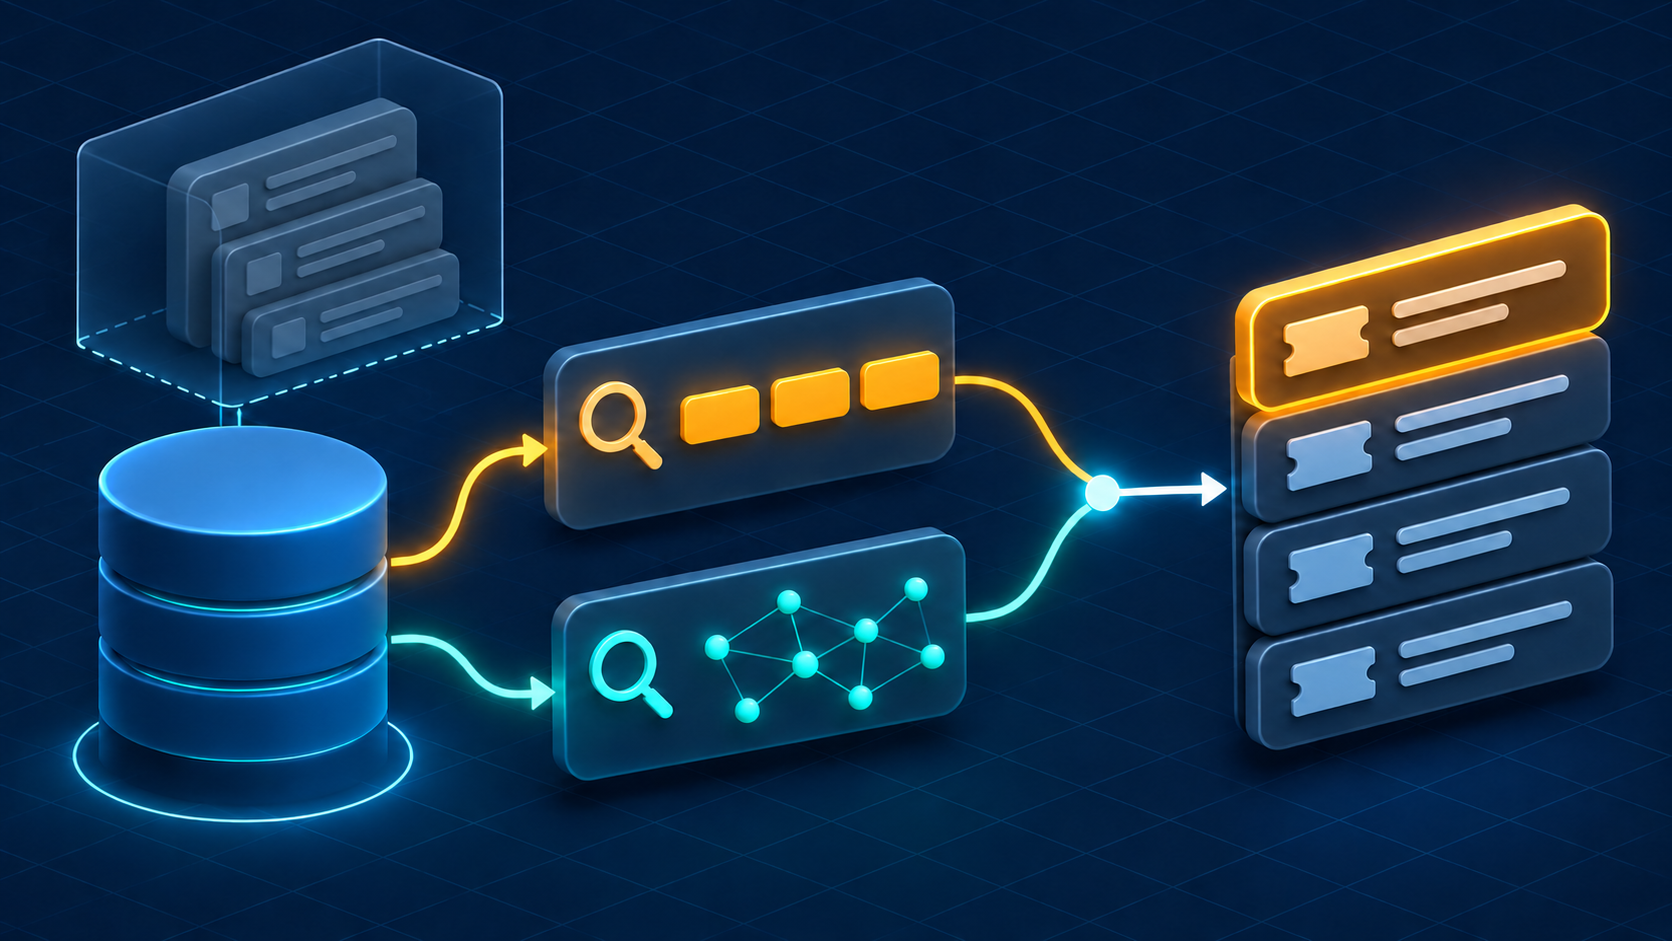
Build PostgreSQL vector search with pgvector and Next.js. Compare keyword and hybrid ranking, enforce tenant access, and reproduce filtered HNSW recall.
A support engineer searches for AUTH-4017. The most useful result is the ticket with that exact error code. Another engineer types “sign-in works until I close the browser” and wants the ticket about a session cookie disappearing on restart. These queries need different kinds of evidence. A useful search feature can combine both without sending the entire support archive to a model.
This guide builds keyword, vector, and hybrid retrieval in PostgreSQL, then connects the query to a Next.js Route Handler. The lab uses fixed, three-dimensional vectors so you can reproduce the ranking and filtering behavior without an embedding API key. Those numbers stand in for embeddings; they do not measure an embedding model’s understanding of support tickets.
Create a small support-ticket search lab
Use a disposable PostgreSQL database with pgvector 0.8 or newer. A provider that supports the extension or a local image from the pgvector project works. The extension and schema setup require a migration role; the search route will use a separate, restricted login.
CREATE EXTENSION IF NOT EXISTS vector; CREATE TABLE support_ticket ( id integer GENERATED ALWAYS AS IDENTITY PRIMARY KEY, tenant_id text NOT NULL, error_code text, title text NOT NULL, body text NOT NULL, embedding vector(3) NOT NULL, search_text tsvector GENERATED ALWAYS AS ( setweight(to_tsvector('english', title), 'A') || setweight(to_tsvector('english', body), 'B') ) STORED ); CREATE INDEX ticket_tenant_idx ON support_ticket (tenant_id); CREATE INDEX ticket_code_idx ON support_ticket (tenant_id, error_code); CREATE INDEX ticket_fts_idx ON support_ticket USING gin (search_text); INSERT INTO support_ticket (tenant_id, error_code, title, body, embedding) VALUES ('acme', 'AUTH-4017', 'AUTH-4017: OAuth callback failed', 'Verify the redirect URI registered with the identity provider.', '[0.8,0.6,0]'), ('acme', NULL, 'Session cookie disappears on browser restart', 'Use a persistent cookie with an appropriate expiry.', '[0.99,0.1,0]'), ('acme', NULL, 'Invoice CSV is missing tax columns', 'Check the export schema version.', '[0,1,0]'), ('other', 'AUTH-4017', 'Private OAuth configuration', 'This row must never be returned to Acme.', '[1,0,0]');Keep identifiers in their own indexed field. PostgreSQL full-text search normalizes language; it cannot promise exact matching of every punctuation-heavy error code or SKU. The text search documentation explains tokenization and weighting. Here the title contributes more than the body, and an exact code has its own match path.
Compare keyword search and exact vector search
Keyword search is a good baseline for distinctive words, product names, and identifiers. Vector search orders by distance to a query vector; it can retrieve text that shares few words with the query. Both queries bind the tenant before returning candidates.
SELECT id, title FROM support_ticket WHERE tenant_id = $1 AND ( error_code = upper($2) OR search_text @@ websearch_to_tsquery('english', $2) ) ORDER BY coalesce(error_code = upper($2), false) DESC, ts_rank_cd(search_text, websearch_to_tsquery('english', $2)) DESC, id LIMIT 20;SELECT id, title, embedding <=> $2::vector AS distance FROM support_ticket WHERE tenant_id = $1 ORDER BY embedding <=> $2::vector LIMIT 3;Before creating an approximate index, the vector query is an exact baseline. Use a parameterized client to run the keyword query with Acme and AUTH-4017, and the vector query with Acme and [1,0,0]. With these fixtures the keyword query returns ticket 1, while vector search ranks ticket 2 above ticket 1. The private ticket has a closer vector than either, but is outside the tenant filter.
Now try the paraphrase “sign-in works until I close the browser” with the same query vector. The keyword query finds no matching row because its required terms are not all present. The fixture vector retrieves the session-cookie ticket first. In a real system you would generate different query vectors for those two strings; reusing one here deliberately holds the vector side constant.
Combine the lists with pgvector hybrid search
A text rank and a cosine distance have different meanings and scales. Reciprocal rank fusion (RRF) uses a candidate’s position in each list instead of adding the raw scores. A candidate gets 1 divided by a constant plus its rank for each list it appears in. A missing candidate contributes zero. This gives you a baseline you can tune with judged queries.
WITH keyword_hits AS MATERIALIZED ( SELECT id, coalesce(error_code = upper($2), false) AS exact_code, ts_rank_cd(search_text, websearch_to_tsquery('english', $2)) AS text_rank FROM support_ticket WHERE tenant_id = $1 AND ( error_code = upper($2) OR search_text @@ websearch_to_tsquery('english', $2) ) ORDER BY exact_code DESC, text_rank DESC, id LIMIT 20 ), vector_hits AS MATERIALIZED ( SELECT id, embedding <=> $3::vector AS distance FROM support_ticket WHERE tenant_id = $1 ORDER BY embedding <=> $3::vector LIMIT 20 ), contributions AS ( SELECT id, 1.0 / (60 + row_number() OVER ( ORDER BY exact_code DESC, text_rank DESC, id )) AS score, exact_code FROM keyword_hits UNION ALL SELECT id, 1.0 / (60 + row_number() OVER (ORDER BY distance, id)), false FROM vector_hits ), fused AS ( SELECT id, sum(score) AS score, bool_or(exact_code) AS exact_code FROM contributions GROUP BY id ) SELECT t.id, t.title, f.score::double precision AS score FROM fused f JOIN support_ticket t ON t.id = f.id AND t.tenant_id = $1 ORDER BY f.exact_code DESC, f.score DESC, t.id LIMIT 5;This example promotes exact codes before applying fusion so the identifier still wins when a semantic match is close. For ordinary queries, the fused rank determines the order. With Acme, AUTH-4017, and [1,0,0], the hybrid query returns ticket 1 first. For the paraphrase, the lexical list is empty and the vector list supplies the results.
Do not treat the fused score as a confidence percentage. A top result can still be wrong, particularly when neither branch has strong evidence. For a retrieval-augmented agent, keep the source ID with every retrieved item, and decide when to return “no reliable match” using evaluated queries rather than a magic score threshold.
Enforce tenant access at the database boundary
Filter both candidate lists. Filtering only after taking the top 20 across all tenants wastes candidates and makes it easier for a future join to expose another workspace’s data. Add Row Level Security (RLS) as a second layer. The app supplies the tenant from its authenticated membership check, never from a client-controlled search parameter.
CREATE ROLE support_search NOLOGIN; GRANT USAGE ON SCHEMA public TO support_search; GRANT SELECT ON support_ticket TO support_search; ALTER TABLE support_ticket ENABLE ROW LEVEL SECURITY; CREATE POLICY support_search_tenant ON support_ticket FOR SELECT TO support_search USING (tenant_id = nullif(current_setting('app.tenant_id', true), ''));Provision a dedicated runtime login that inherits support_search. It must not own the table or have BYPASSRLS, superuser privileges, or broader inherited grants. With no transaction tenant setting, the policy returns no rows. Test through that role, since a successful query as the table owner says nothing about RLS.
A custom session setting is only as trustworthy as the code setting it. This pattern assumes the application owns the database connection and runs fixed, parameterized SQL; it is unsuitable as a sandbox for arbitrary SQL from an agent. See the least-privilege PostgreSQL guide for the role and permission checks.
Connect the query to a Next.js Route Handler
Install pg and its TypeScript types. Keep the SQL as a static server-side constant exported from your application’s search-query module. The example uses a Node.js route; auth and the embedding provider are your app’s adapters. The provider must return a vector in the same space as the stored embeddings. The three-element check below is for the lab; production uses the dimension of the selected model.
import { Pool } from 'pg' import { getVerifiedTenantId } from '@/lib/auth' import { embedSupportQuery } from '@/lib/embeddings' import { hybridSearchSql } from '@/lib/search-query' export const runtime = 'nodejs' const connectionString = process.env.SUPPORT_SEARCH_DATABASE_URL if (!connectionString) throw new Error('Missing SUPPORT_SEARCH_DATABASE_URL') const pool = new Pool({ connectionString, max: 3, connectionTimeoutMillis: 2000 }) export async function POST(request: Request) { const tenantId = await getVerifiedTenantId(request) if (!tenantId) return Response.json({ error: 'Unauthorized' }, { status: 401 }) const payload: unknown = await request.json().catch(() => null) const q = payload && typeof payload === 'object' && 'q' in payload && typeof payload.q === 'string' ? payload.q.trim() : '' if (!q || q.length > 400) { return Response.json({ error: 'Enter a query of 1–400 characters' }, { status: 400 }) } const embedding = await embedSupportQuery(q, request.signal) if (embedding.length !== 3 || !embedding.every(Number.isFinite) || embedding.every(value => value === 0)) { throw new Error('Embedding has an unexpected shape') } const client = await pool.connect() let discard = false try { await client.query('BEGIN') await client.query("SET LOCAL statement_timeout = '1500ms'") await client.query("SELECT set_config('app.tenant_id', $1, true)", [tenantId]) const result = await client.query(hybridSearchSql, [ tenantId, q, JSON.stringify(embedding), ]) await client.query('COMMIT') return Response.json(result.rows, { headers: { 'Cache-Control': 'private, no-store' } }) } catch (error) { try { await client.query('ROLLBACK') } catch { discard = true } throw error } finally { client.release(discard) } }When using a connection pool, every statement in the transaction must use the same checked-out client. The third argument to set_config makes the tenant setting transaction-local, so it cannot carry into the next request. A serverless instance can hold its own pool; budget the total possible connections across instances or use your provider’s pooling endpoint.
Measure how tenant filters change HNSW recall
An HNSW index can speed up vector lookups, but it retrieves approximate candidates. As the pgvector filtering notes describe, a restrictive predicate can discard candidates after the index scan. A low-selectivity tenant filter can therefore produce fewer rows than requested even when the tenant has enough rows.
Add a dense group of other-tenant vectors close to the query. The original Acme vectors remain unchanged. Build an HNSW index with the cosine operator class so it matches the distance operator used above.
INSERT INTO support_ticket (tenant_id, title, body, embedding) SELECT 'other', 'Private fixture ' || n, 'Approximate-index test row', format('[1,%s,0.001]', n / 100000.0)::vector FROM generate_series(1, 500) AS s(n); CREATE INDEX ticket_embedding_hnsw ON support_ticket USING hnsw (embedding vector_cosine_ops); ANALYZE support_ticket;Save the three IDs from the exact baseline before creating the index. After adding it, inspect EXPLAIN (ANALYZE, BUFFERS) for the same vector query. A tiny, selective tenant can reasonably use its B-tree filter and sort the eligible rows. That is a good production outcome, but it does not test HNSW. For the lab, temporarily disable competing paths and make sure the plan names ticket_embedding_hnsw.
BEGIN; -- Lab only: the tiny tenant is cheaper to search exactly. -- Adjust planner settings and confirm the index with EXPLAIN. SET LOCAL enable_seqscan = off; SET LOCAL enable_bitmapscan = off; SET LOCAL enable_sort = off; SET LOCAL hnsw.ef_search = 40; SET LOCAL hnsw.iterative_scan = off; EXPLAIN (ANALYZE, BUFFERS) SELECT id FROM support_ticket WHERE tenant_id = 'acme' ORDER BY embedding <=> '[1,0,0]'::vector LIMIT 3; SELECT id FROM support_ticket WHERE tenant_id = 'acme' ORDER BY embedding <=> '[1,0,0]'::vector LIMIT 3; SET LOCAL hnsw.iterative_scan = strict_order; SELECT id FROM support_ticket WHERE tenant_id = 'acme' ORDER BY embedding <=> '[1,0,0]'::vector LIMIT 3; ROLLBACK;For each run, record how many eligible rows are returned and recall@3: the number of returned IDs that also appear in the exact top three, divided by three. Compare the same tenant, query vector, and limit. This is nearest-neighbor recall, not a judgment of answer relevance. Use human relevance labels to evaluate keyword versus hybrid ranking.
Mode Returned IDs Rows Recall@3 Exact 2, 1, 3 3 3/3 HNSW, iterative scan off none 0 0/3 HNSW, strict iterative scan 2, 1, 3 3 3/3The experiment ran on the PGlite PostgreSQL runtime with a confirmed HNSW plan. The fixture deliberately packs other-tenant vectors near the query, so it illustrates the filtering failure mode rather than forecasting your recall or latency.
To reproduce it without a separate database, save the seven SQL blocks under their shown filenames, install the two PGlite packages in a scratch directory, and run this script there with Node.js. It creates a fresh in-memory database.
npm install @electric-sql/pglite@0.5.16 @electric-sql/pglite-pgvector@0.0.17 node lab.mjsimport { readFile } from 'node:fs/promises' import { PGlite } from '@electric-sql/pglite' import { vector } from '@electric-sql/pglite-pgvector' const db = await PGlite.create({ extensions: { vector } }) const sql = name => readFile(new URL(name, import.meta.url), 'utf8') const vectorInput = '[1,0,0]' try { await db.exec(await sql('01-schema.sql')) for (const query of ['AUTH-4017', 'sign-in works until I close the browser']) { const keyword = await db.query(await sql('02-keyword.sql'), ['acme', query]) const exact = await db.query(await sql('03-vector.sql'), ['acme', vectorInput]) const hybrid = await db.query(await sql('04-hybrid.sql'), ['acme', query, vectorInput]) console.log({ query, keyword: keyword.rows, exact: exact.rows, hybrid: hybrid.rows }) } await db.exec(await sql('05-rls.sql')) await db.exec(await sql('06-hnsw-fixture.sql')) for (const result of await db.exec(await sql('07-compare-hnsw.sql'))) { if (result.fields.length) console.log(result.rows) } } finally { await db.close() }The lab runs as the migration role. Use the restricted-role checks described above to verify tenant enforcement independently of the application filters.
Iterative scans can explore more of the index after filtering, within their scan limits. They cannot promise exact recall. In production, compare exact search over a small tenant, ordinary HNSW, and iterative HNSW using representative tenant sizes. Keep the measured query plan, recall, and latency together so you can tell what improved and what it cost.
Move from fixture vectors to real embeddings
Choose one embedding model and dimension, backfill your document vectors, and use the same model for queries. Track the embedding model and document revision alongside each row. Re-embed on content changes and delete derived vectors when the source is deleted. A model migration needs a new index or separate versioned vector storage so you never compare vectors from incompatible spaces.
Give the query embedding call its own deadline and cap user input, returned candidates, and result fields. You can offer lexical search when the embedding provider is unavailable, and make that fallback visible in logs. For a customer-facing endpoint, enforce request-size and rate limits before spending money on inference.
Start with a small evaluation set: exact codes, paraphrases, ambiguous queries, missing answers, and two tenants with nearly identical documents. Measure retrieval separately from model generation. You can plug the resulting bounded search tool into the AI SDK 7 support agent once those checks pass.


