AI & ML
Towards Universal Tabular Embeddings: A Benchmark Across Data Tasks
arXiv cs.DB0 views
arXiv:2604.21696v3 Announce Type: replace-cross Abstract: Tabular foundation models aim to learn universal representations of tabular data that transfer across tasks and domains, enabling applications such as table retrieval, semantic search and table-based prediction. Despite the growing number of such models, it remains unclear which approach works best in practice, as existing methods are often evaluated under task-specific settings that make direct comparison difficult. To address this, we introduce TEmBed, the Tabular Embedding Test Bed, a unified benchmark for systematically evaluating tabular embeddings across four representation levels: cell, row, column, and table. Evaluating a diverse set of tabular representation learning models, we show that which model to use depends on the task and representation level. Our results offer practical guidance for selecting tabular embeddings in real-world applications and lay the groundwork for developing more general-purpose tabular representation models.
Source:https://arxiv.org/abs/2604.21696PreviousTessera: Fast Join-Aggregates over Skewed Sparse Relations in Database EnginesNextHow Cloud-Edge AI Works on Low-Resource Feature Phones
Related posts
Congresswoman calls for artificial superintelligence ban after Democrats' seismic midterm sweep
0Tom's Hardware
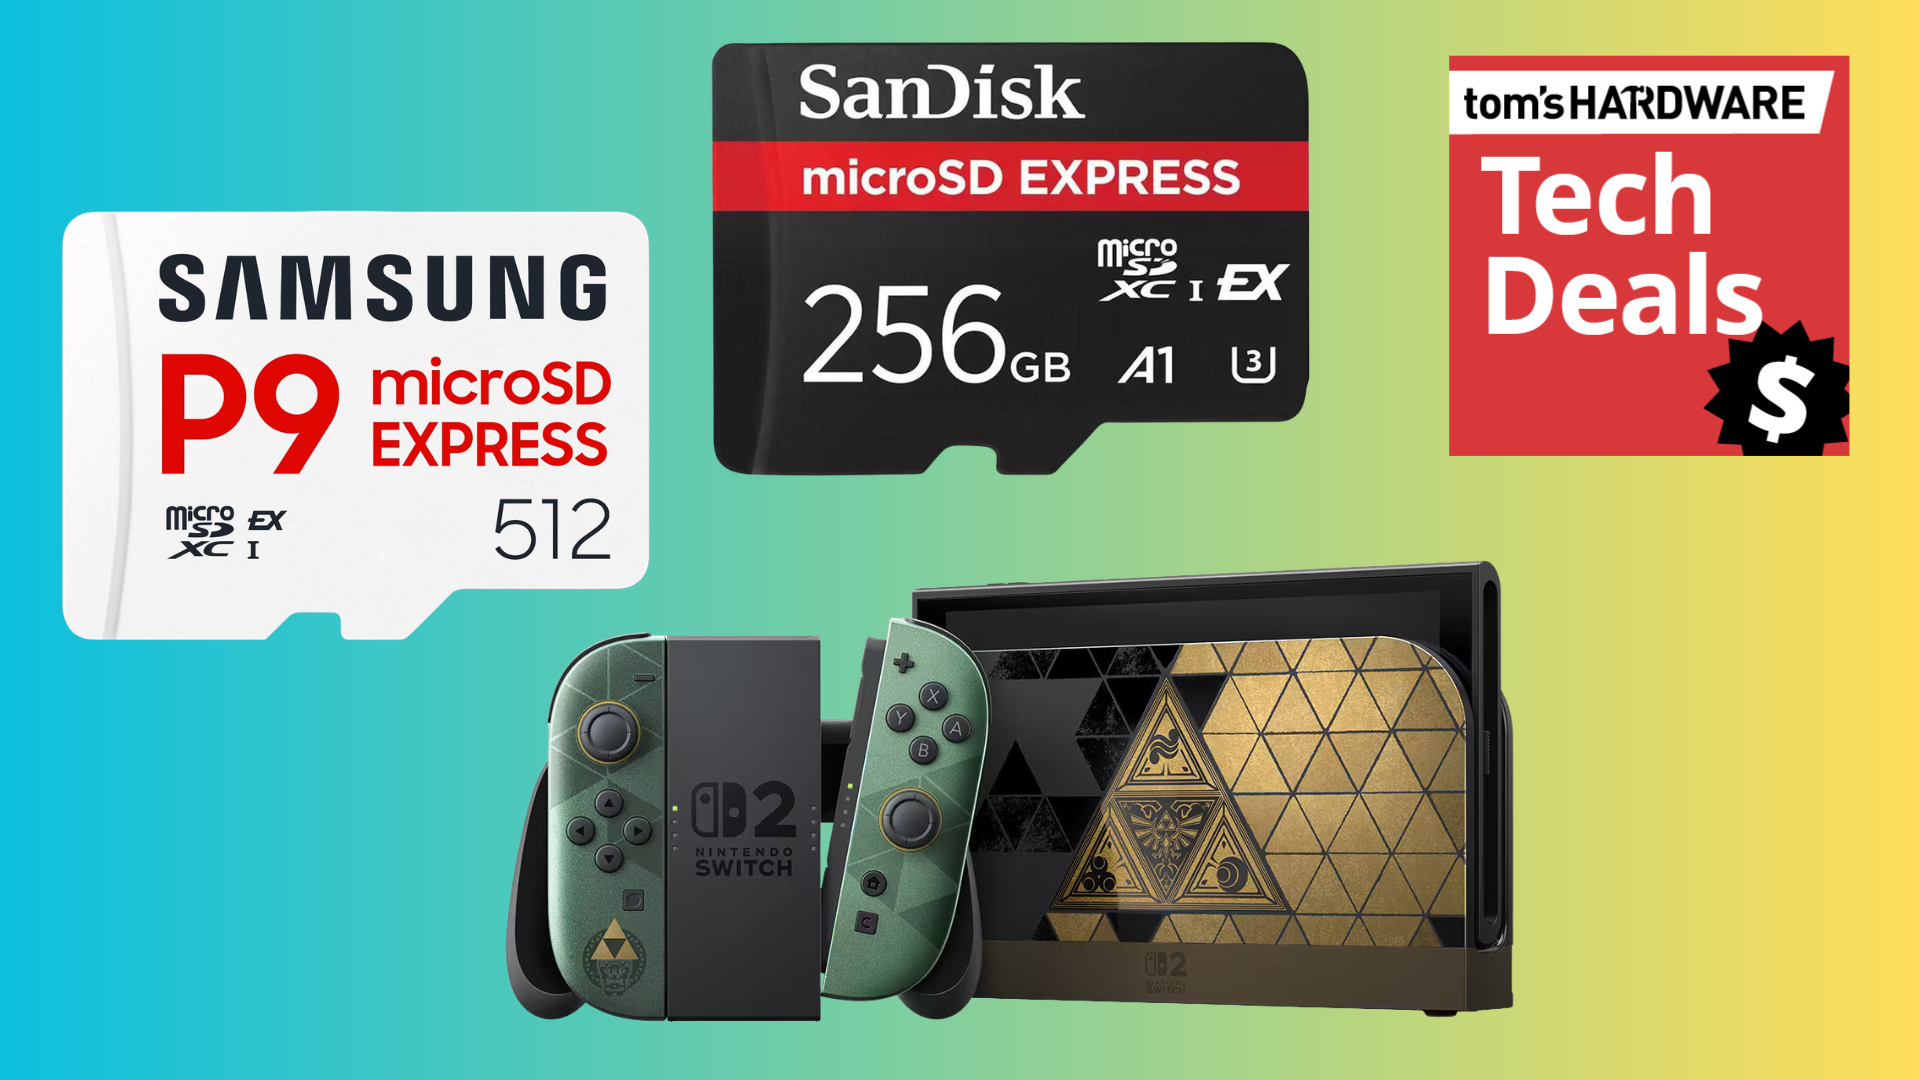
Boost your Nintendo Switch 2's storage for Zelda: Ocarina of Time with these microSD Express deals, starting at $48
0Tom's Hardware

AWS MLA-C01 to MLA-C02: What's Changing and What to Do Now
0dev.to

How to Create Videos With Google Antigravity CLI
0dev.to

Finding New Drugs Is Laborious. This AI Startup Is Skipping The Lab Work
0Wired

Spotify is coming to United Airlines seatbacks — with help from Starlink
0The Verge