AI & ML
3D-MoE: Towards Spatial Intelligence with Mixture-of-Experts for 3D Reasoning and Action Generation
arXiv cs.RO0 views
arXiv:2501.16698v3 Announce Type: replace-cross Abstract: Spatial intelligence, encompassing 3D perception and reasoning, is the essential next frontier of AI. Scaling current 3D vision-language models (VLMs) that rely on dense Transformers for spatial tasks incurs prohibitive computational costs. In this paper, we introduce 3D-MoE, a 3D VLM leveraging an efficient mixture-of-experts architecture with a modality- and spatial-context-aware probabilistic routing scheme, stably cultivated by a novel routing curriculum. To seamlessly extend 3D-MoE to embodied AI, we integrate a diffusion-based action head, Pose-DiT, transforming 3D-MoE into a 3D vision-language-action (VLA) model. By employing a rectified flow framework, Pose-DiT generates precise 6D pose actions in a single sampling step. Extensive experiments demonstrate that 3D-MoE achieves superior performance on diverse 3D vision-language benchmarks with drastically fewer activated parameters and yields higher success rates while enabling real-time inference for robot manipulation tasks. Code is available at https://github.com/yueen-ma/3D-MoE.
Source:https://arxiv.org/abs/2501.16698PreviousXBot-Omni: An Omni-Modal Model for Embodied Understanding and InteractionNextParallel Branch Model Predictive Control on GPUs
Related posts
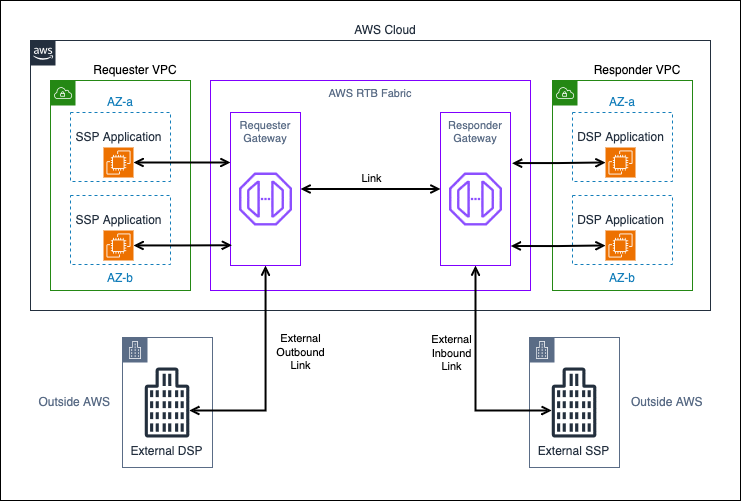
Building highly available real-time bidding workloads with AWS RTB Fabric
0AWS for Industries

Thống kê đối đầu Rayo Vallecano vs Valencia: Xu thế bế tắc và quy luật chia điểm áp đảo
0dev.to Data

Phân tích dữ liệu đối đầu Alaves vs Deportivo La Coruna: Ưu thế phòng ngự tuyệt đối của đại diện xứ Basque
0dev.to Data

Thống kê đối đầu Arsenal vs Newcastle: Thế trận phân định tuyệt đối và dấu ấn phòng ngự
0dev.to Data

Tương quan thông số vòng 8 V.League 1: Thể Công - Viettel chạm trán Sông Lam Nghệ An
0dev.to Data

Into the Breach: Show the Threat, Not the Answer
0dev.to Design