AI & ML
STRIDE: Learning Humanoid Locomotion in Minutes with Acceleration-Based Rewards
arXiv cs.RO0 views
arXiv:2611.08857v1 Announce Type: new Abstract: Learning locomotion directly on a humanoid robot is a promising direction to avoid the sim-to-real gap. However, locomotion rewards in Reinforcement Learning (RL) typically track the base velocity, which cannot be measured onboard without an external motion capture system or well-calibrated state estimator. This is why we introduce \method{}, which learns humanoid locomotion from minutes of samples with a reward that only requires the onboard Inertial Measurement Unit (IMU). Instead of tracking the base velocity, STRIDE rewards the robot for following a commanded acceleration profile. To learn efficiently from this reward, we use the off-policy RL algorithm XQC and combine a high gain setting for the joint position controllers with left-right symmetry augmentation. In simulation, STRIDE learns to walk on the Unitree G1 and Booster T1 humanoids within 14 minutes of samples. Compared to learning without these two components, it reduces the falls during training by 81%, while without them the robot learns only in over an hour.
Source:https://arxiv.org/abs/2611.08857PreviousActPrune: Action-Grounded Visual Token Pruning for Efficient Vision-Language-Action ModelsNextWhat Limits mmWave Human-State Sensing for Robot Perception?
Related posts
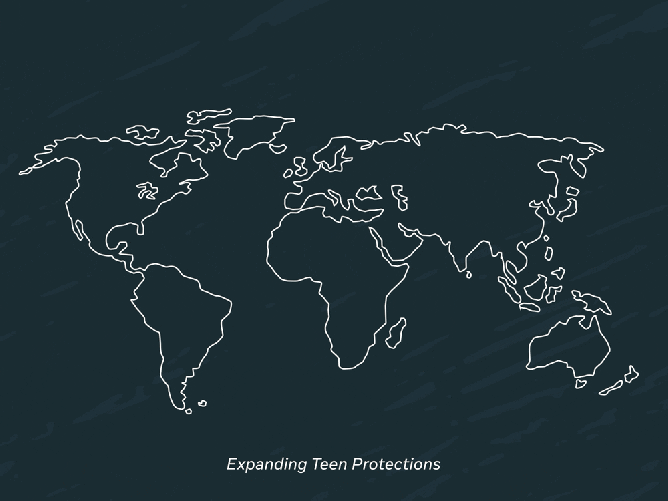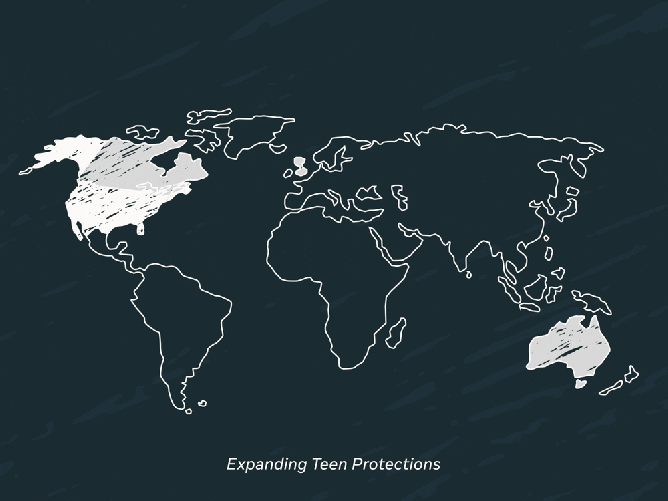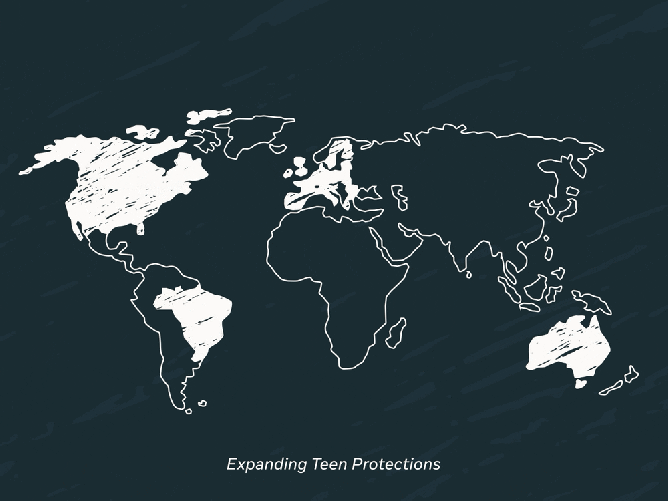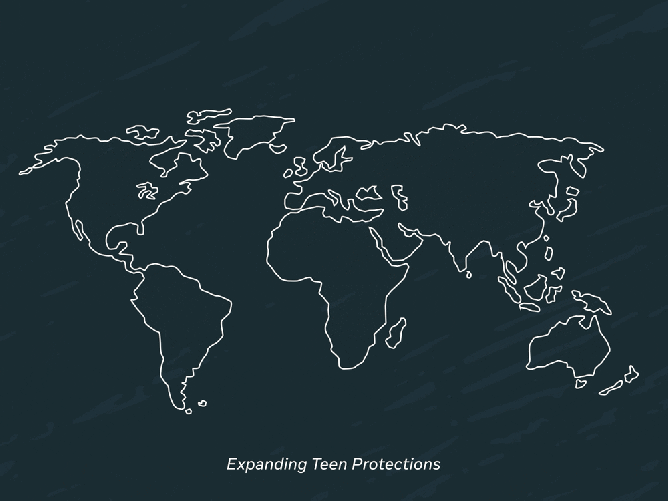
Expanding Teen Account Protections to Teens Around the World
0Meta Newsroom

Tối ưu hóa hiệu suất đầu ra: Tiền vệ Njie vực dậy hàng công Fiorentina với 5 lần in dấu giày
0dev.to Data

Hiệu suất săn bàn ấn tượng của Gouiri thúc đẩy chuỗi toàn thắng của Marseille
0dev.to Data

Hiệu suất săn bàn vượt trội của Kylian Mbappé trong màu áo Real Madrid
0dev.to Data

Hiệu suất toàn diện đưa Harry Kane vượt mặt Kylian Mbappe và Lamine Yamal trên bình diện thế giới
0dev.to Data

How Many .com Names Appear and Disappear Each Day?
0dev.to Data